<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" xml:lang="en-US"><generator uri="https://jekyllrb.com/" version="4.4.1">Jekyll</generator><link href="https://paolino.me/feed.xml" rel="self" type="application/atom+xml" /><link href="https://paolino.me/" rel="alternate" type="text/html" hreflang="en-US" /><updated>2026-11-11T23:55:57+00:00</updated><id>https://paolino.me/feed.xml</id><title type="html">Carmine Paolino</title><subtitle>I build AI products, frameworks, developer tools, and native apps at Plenty. Creator of RubyLLM, Berlin.rb organizer, and founder of the Floppy Disco music collective.</subtitle><author><name>Carmine Paolino</name></author><entry><title type="html">RubyLLM 2.2: The AI Framework for Coding Agents</title><link href="https://paolino.me/rubyllm-2-2/" rel="alternate" type="text/html" title="RubyLLM 2.2: The AI Framework for Coding Agents" /><published>2026-11-10T22:15:00+00:00</published><updated>2026-11-11T23:53:01+00:00</updated><id>https://paolino.me/rubyllm-2-2</id><content type="html" xml:base="https://paolino.me/rubyllm-2-2/"><![CDATA[<p><a href="https://rubyllm.com">RubyLLM</a> 2.2 is out! I released it on stage at SF Ruby, and it’s the release I’m proudest of.</p>

<p>The code a model writes now runs in a sandbox on your own servers, and skills and file stores build on it. Tools can ask a person and wait for the answer. A chat survives a deploy. And there are context budgets, tests without a provider, and four new providers.</p>

<p>It’s also the first release I built for a new kind of user: the coding agent. More and more of the code that uses RubyLLM is written by Claude Code, Codex and Cursor, so I spent as much time making RubyLLM easy for them to use as I did on features. The talk was about that, and about the idea that you don’t need frameworks anymore.</p>

<p>Here’s what’s new.</p>

<h2 id="code-in-a-sandbox-on-your-own-servers">Code in a Sandbox, on Your Own Servers</h2>

<p>A model that can run code calculates exactly, reshapes your data, and makes charts, spreadsheets and PDFs. But that code was written by a model, so it should never run in your app’s process.</p>

<p>So I made a new gem, <a href="https://crmne.github.io/mxc/">mxc</a>: Microsoft’s MXC, from Ruby, and improved. It uses the operating system’s own isolation, Bubblewrap on Linux and Seatbelt on macOS, and you can bound everything: files, network, CPU time, memory. I think it’s really beautiful code:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">class</span> <span class="nc">WorkspaceSandbox</span> <span class="o">&lt;</span> <span class="no">MXC</span><span class="o">::</span><span class="no">Sandbox</span>
  <span class="n">writable</span> <span class="s2">"storage/workspace"</span>
  <span class="n">network</span> <span class="kp">false</span>
  <span class="n">timeout</span> <span class="mi">120</span>
  <span class="n">limits</span> <span class="ss">cpu_time: </span><span class="mi">60</span><span class="p">,</span> <span class="ss">memory: </span><span class="mi">1</span><span class="p">.</span><span class="nf">gigabyte</span>
<span class="k">end</span>

<span class="n">chat</span> <span class="o">=</span> <span class="no">RubyLLM</span><span class="p">.</span><span class="nf">chat</span><span class="p">.</span><span class="nf">with_code_execution</span><span class="p">(</span><span class="ss">sandbox: </span><span class="no">WorkspaceSandbox</span><span class="p">,</span> <span class="ss">python: </span><span class="sx">%w[pandas matplotlib]</span><span class="p">)</span>
<span class="n">chat</span><span class="p">.</span><span class="nf">ask</span> <span class="s2">"Plot monthly revenue from this export"</span><span class="p">,</span> <span class="ss">with: </span><span class="s2">"revenue.csv"</span>
</code></pre></div></div>

<p>The files the code makes come back as attachments. See <a href="https://rubyllm.com/code-execution/">Code Execution</a>.</p>

<h2 id="skills">Skills</h2>

<p>Some tasks need a procedure, not a sentence: how your company formats an invoice, or the script that turns a spreadsheet into slides. Skills keep them in folders, in the open format every coding agent speaks, and the model loads one only when a task needs it. With code execution, their scripts run in the sandbox.</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">chat</span> <span class="o">=</span> <span class="no">RubyLLM</span><span class="p">.</span><span class="nf">chat</span><span class="p">.</span><span class="nf">with_skills</span><span class="p">(</span><span class="ss">:invoices</span><span class="p">).</span><span class="nf">with_code_execution</span><span class="p">(</span><span class="ss">python: </span><span class="sx">%w[reportlab]</span><span class="p">)</span>
<span class="n">chat</span><span class="p">.</span><span class="nf">ask</span> <span class="s2">"Bill order 1042 to ACME"</span><span class="p">,</span> <span class="ss">with: </span><span class="s2">"order-1042.json"</span>
</code></pre></div></div>

<p>And why should we use <code class="language-plaintext highlighter-rouge">npx skills</code> when we have Ruby? I made the <a href="https://github.com/crmne/skill">skill</a> gem. It installs skills into your coding agent, and into your Rails app, with a <code class="language-plaintext highlighter-rouge">skills.lock</code>. RubyLLM ships its own skill inside the gem, so Claude Code, Codex or Cursor learn the RubyLLM way with one command:</p>

<div class="language-sh highlighter-rouge"><div class="highlight"><pre class="highlight"><code>gem <span class="nb">exec </span>skill add <span class="s2">"</span><span class="si">$(</span>bundle show ruby_llm<span class="si">)</span><span class="s2">"</span> <span class="nt">--skill</span> rubyllm <span class="nt">--agents</span> coding
</code></pre></div></div>

<h2 id="file-stores">File Stores</h2>

<p>That 40-page PDF you attached to the first question? It used to travel with every question after it. With a file store, the model sees it once and then works with it through tools, like a coding agent does: list, search, read, write, edit.</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">chat</span> <span class="o">=</span> <span class="no">RubyLLM</span><span class="p">.</span><span class="nf">chat</span><span class="p">.</span><span class="nf">with_file_store</span>
<span class="n">chat</span><span class="p">.</span><span class="nf">ask</span> <span class="s2">"Which clauses changed?"</span><span class="p">,</span> <span class="ss">with: </span><span class="p">[</span><span class="s2">"contract-v1.pdf"</span><span class="p">,</span> <span class="s2">"contract-v2.pdf"</span><span class="p">]</span>
<span class="n">chat</span><span class="p">.</span><span class="nf">ask</span> <span class="s2">"Quote the new termination clause"</span>
</code></pre></div></div>

<p>With code execution, the code runs in the store’s folder, like a coding agent’s workspace, and what it writes is saved back. See <a href="https://rubyllm.com/file-stores/">File Stores</a>.</p>

<h2 id="tools-ask-a-person">Tools Ask a Person</h2>

<p>Window or aisle? A tool can now ask the person running the chat, and carry on with the answer. The call pauses, no process sits there waiting, and when they answer, <code class="language-plaintext highlighter-rouge">execute</code> runs again from the top. So: ask first, then act.</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">class</span> <span class="nc">BookFlight</span> <span class="o">&lt;</span> <span class="no">RubyLLM</span><span class="o">::</span><span class="no">Tool</span>
  <span class="n">description</span> <span class="s2">"Books a flight"</span>
  <span class="n">parameter</span> <span class="ss">:destination</span><span class="p">,</span> <span class="ss">description: </span><span class="s2">"The city to fly to"</span>

  <span class="k">def</span> <span class="nf">execute</span><span class="p">(</span><span class="n">destination</span><span class="p">:)</span>
    <span class="n">seat</span> <span class="o">=</span> <span class="n">ask</span><span class="p">(</span><span class="s2">"Window or aisle?"</span><span class="p">,</span> <span class="ss">choices: </span><span class="sx">%w[window aisle]</span><span class="p">)</span> <span class="ow">or</span> <span class="k">return</span> <span class="s2">"No seat chosen."</span>
    <span class="no">Flights</span><span class="p">.</span><span class="nf">book!</span><span class="p">(</span><span class="n">destination</span><span class="p">,</span> <span class="n">seat</span><span class="p">:)</span>
  <span class="k">end</span>
<span class="k">end</span>
</code></pre></div></div>

<p>An approval is just a question with yes and no, and MCP servers ask theirs the same way. From any process, three verbs: answer, approve, or decline with a note so the model knows why.</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">question</span> <span class="o">=</span> <span class="n">chat</span><span class="p">.</span><span class="nf">pending_questions</span><span class="p">.</span><span class="nf">first</span>

<span class="n">question</span><span class="p">.</span><span class="nf">answer</span> <span class="s2">"window"</span>
<span class="n">question</span><span class="p">.</span><span class="nf">approve</span> <span class="ss">remember: </span><span class="kp">true</span>
<span class="n">question</span><span class="p">.</span><span class="nf">decline</span> <span class="s2">"I'll choose at the gate"</span>

<span class="n">chat</span><span class="p">.</span><span class="nf">complete</span>
</code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">remember: true</code> means your users don’t get asked again for that tool. <a href="https://rubyllm.com/tool-execution/#asking-a-person">Asking a Person</a> has the rest.</p>

<h2 id="a-chat-survives-a-deploy">A Chat Survives a Deploy</h2>

<p>Chats are long-running background jobs. So what happens when you deploy in the middle of a reply?</p>

<p>Now a persisted chat runs in one process at a time, so a double click never runs a tool twice. If a deploy or a crash cuts off a reply, <code class="language-plaintext highlighter-rouge">Chat.interrupted</code> finds it, and the generated <code class="language-plaintext highlighter-rouge">ResumeInterruptedChatsJob</code> picks it up as soon as the server boots:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="no">Chat</span><span class="p">.</span><span class="nf">interrupted</span><span class="p">.</span><span class="nf">find_each</span> <span class="p">{</span> <span class="o">|</span><span class="n">chat</span><span class="o">|</span> <span class="no">ChatResponseJob</span><span class="p">.</span><span class="nf">perform_later</span><span class="p">(</span><span class="n">chat</span><span class="p">.</span><span class="nf">id</span><span class="p">)</span> <span class="p">}</span>
</code></pre></div></div>

<p>And a tool call that had already started never runs again. The model hears it may have partly run, and decides what to do. See <a href="https://rubyllm.com/durable-agents/">Agents in Background Jobs</a>.</p>

<h2 id="context-budgets">Context Budgets</h2>

<p>One giant tool result used to break the whole chat. Not anymore:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">config</span><span class="p">.</span><span class="nf">context_budget</span> <span class="o">=</span> <span class="p">{</span> <span class="ss">per_result: </span><span class="mf">0.25</span><span class="p">,</span> <span class="ss">per_request: </span><span class="mf">0.7</span> <span class="p">}</span>
</code></pre></div></div>

<p>Results longer than their share get cut, and the oldest ones are left out of a request that would be too big, while keeping the prompt cache warm. New Rails apps get this line from the generator.</p>

<h2 id="tests-without-a-provider">Tests Without a Provider</h2>

<p>A really requested one. Script what the model says, and test your real chats, agents and pages with no provider and no API key:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">stub_replies</span> <span class="n">tool_call</span><span class="p">(</span><span class="ss">:weather</span><span class="p">,</span> <span class="ss">city: </span><span class="s2">"Berlin"</span><span class="p">),</span> <span class="s2">"It is sunny."</span><span class="p">,</span> <span class="ss">cost: </span><span class="mf">0.01</span>
<span class="n">assert_equal</span> <span class="s2">"It is sunny."</span><span class="p">,</span> <span class="no">SupportAgent</span><span class="p">.</span><span class="nf">new</span><span class="p">.</span><span class="nf">ask</span><span class="p">(</span><span class="s2">"Weather?"</span><span class="p">).</span><span class="nf">content</span>
</code></pre></div></div>

<h2 id="a-generator-for-every-building-block">A Generator for Every Building Block</h2>

<p>Agents, tools, schemas, MCP servers, skills, sandboxes, evaluations and judges:</p>

<div class="language-sh highlighter-rouge"><div class="highlight"><pre class="highlight"><code>bin/rails generate ruby_llm:mcp Linear https://mcp.linear.app/mcp
bin/rails generate ruby_llm:skill invoices <span class="s2">"Bills an order to a customer as a PDF."</span>
bin/rails generate ruby_llm:sandbox Workspace
</code></pre></div></div>

<p>And the generated chat UI now lets you switch models in the middle of a conversation, and shows a card for every question a tool asks.</p>

<h2 id="twenty-three-providers">Twenty-Three Providers</h2>

<p>Moonshot AI, MiniMax, Z.ai and Meta join. That’s twenty-three providers and 518 provider features built in, each checked against the provider’s own docs. <a href="https://rubyllm.com/provider-coverage/">The coverage table</a> has every one.</p>

<p>There’s a lot more, like queued messages, subagents and exclusive tools, in <a href="https://rubyllm.com/whats-new-in-2-2/">What’s New in 2.2</a>.</p>

<h2 id="where-it-all-comes-from">Where It All Comes From</h2>

<p>DHH didn’t design a web framework in a room. He built Basecamp and pulled out what kept working. RubyLLM comes from <a href="https://chatwithwork.com">Chat with Work</a> the same way. Every feature in 2.2 earned its place there first: bots that ask before they act, survive deploys, run code and work with your files.</p>

<h2 id="upgrading">Upgrading</h2>

<div class="language-sh highlighter-rouge"><div class="highlight"><pre class="highlight"><code>bundle update ruby_llm
bin/rails generate ruby_llm:upgrade
bin/rails db:migrate
</code></pre></div></div>

<p>A few names changed: <code class="language-plaintext highlighter-rouge">pending_questions</code> replaces the separate lists of approvals and inputs, and <code class="language-plaintext highlighter-rouge">decline</code> replaces <code class="language-plaintext highlighter-rouge">deny</code>. <a href="https://rubyllm.com/upgrading/">The upgrade guide</a> has each one.</p>

<p>Still on 1.16? You’re missing a lot: tool approvals, cancel, fallbacks and the cost ledger in 2.0, then a real MCP client, judgments, evaluations and OpenTelemetry in 2.1. Upgrade one release at a time.</p>

<p>Try it, and tell me what you find.</p>]]></content><author><name>Carmine Paolino</name></author><category term="Ruby" /><category term="AI" /><category term="LLM" /><category term="Rails" /><category term="Open Source" /><category term="RubyLLM" /><summary type="html"><![CDATA[RubyLLM 2.2 runs the code a model writes in a sandbox on your own servers, adds skills and file stores, lets tools ask a person, keeps a chat alive through a deploy, and is built to be used well by coding agents.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://paolino.me/images/rubyllm-2.2.png" /><media:content medium="image" url="https://paolino.me/images/rubyllm-2.2.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Solco: Stop Preparing Your Tracks, Start Preparing Your Gigs</title><link href="https://paolino.me/solco-private-beta/" rel="alternate" type="text/html" title="Solco: Stop Preparing Your Tracks, Start Preparing Your Gigs" /><published>2026-10-28T14:30:00+00:00</published><updated>2026-10-28T15:17:10+00:00</updated><id>https://paolino.me/solco-private-beta</id><content type="html" xml:base="https://paolino.me/solco-private-beta/"><![CDATA[<p>Some of you may not know this, but I’m a DJ in my free time. I founded <a href="https://floppydisco.live">Floppy Disco</a>, a music collective to bring the magic of Disco and House to Berlin, and I’ve played clubs all over here and in other places in Europe. I love DJing, and my favourite part is finding new music and playing it for people.</p>

<p>Preparing my tracks, however, has never been truly fun. It rather felt like admin: fixing beat grids that were often wrong, fighting clunky software like rekordbox, building playlists by hand, correcting tags and genres, updating playlists, and deciding whether ratings or colours should stand for energy, mood or vocals.</p>

<p>So I said <em>enough</em>, and built <a href="https://getsolco.com">Solco</a> to do that work for me. Today it opens as a private beta.</p>

<h2 id="what-it-does">What it does</h2>

<p>You drop your music in. Solco grids every track, finds its key and loudness, hears its genre and character (energy, drive, dance, vocals and more, each from 0 to 100), fixes its tags and finds your duplicates by their sound. Then it writes the USB drive your Pioneer CDJs and XDJs read. No rekordbox needed, and no laptop in the booth. It also imports from rekordbox, Traktor and Apple Music, and exports Traktor collections and M3U8 playlists.</p>

<p>Everything is analysed on your computer, by a dozen AI models, each built for its own job. Your music never leaves your computer.</p>

<p>There’s also an assistant. Describe the night (“four hours of disco from 10pm, funky openers building to peak disco”) and it proposes a folder of playlists from your own library, in playing order, which you review before it creates anything. Or name a playlist you already have and ask it to build more slowly, or cut it to 90 minutes. It shows you every track it would add, move and remove, and changes nothing until you say so.</p>

<h2 id="the-numbers">The numbers</h2>

<p>Don’t take my word for it. Here’s Solco against rekordbox 7:</p>

<ul>
  <li><strong>The USB stick.</strong> I timed both apps putting the same 493 tracks on the same USB stick for the first time. Solco took <strong>12 minutes</strong>. rekordbox took <strong>three and a half hours</strong>. (Mac mini M4, 250 GB SanDisk stick on FAT32, rekordbox 7.2.6, median of three runs.)</li>
  <li><strong>Beat grids.</strong> Downbeats: 38% better. Beats: 12% better. That’s Solco against rekordbox 7 on the 998 excerpts of <a href="https://github.com/TempoBeatDownbeat/gtzan_tempo_beat">GTZAN</a>, ten genres that researchers annotated by hand. <a href="https://getsolco.com/measured.html">How we measured</a>.</li>
</ul>

<h2 id="a-private-beta-with-a-key-for-each-person">A private beta, with a key for each person</h2>

<p>Solco works with a licence key made for you. I’m letting DJs in from the waitlist in small groups, so I can answer every message and fix what breaks before the next group comes in.</p>

<p>How the keys work:</p>

<ul>
  <li><strong>Join the waitlist</strong> at <a href="https://getsolco.com">getsolco.com</a>. When there’s a seat for you, your key comes by email. Each friend you refer moves you up 5 places.</li>
  <li><strong>Activate it once.</strong> Paste the key into Solco’s first screen. Activating needs the internet once, and then Solco works offline.</li>
  <li><strong>Up to three computers.</strong> Your key is yours alone and works on up to three of your computers.</li>
  <li><strong>It renews itself.</strong> While the beta lasts, your key renews by itself, and new builds with fixes come out often.</li>
</ul>

<p>The private beta is free. It runs on macOS (Apple Silicon), Windows and Linux.</p>

<p>It’s a beta, so keep a backup of your music and use a spare USB stick for your first exports. And tell me what works, what doesn’t and what you wish it did: there’s a Feedback button right in the app, and I read everything at hello@getsolco.com.</p>

<p>Stop preparing your tracks. Start preparing your gigs.</p>

<p><strong><a href="https://getsolco.com">Join the private beta</a></strong></p>]]></content><author><name>Carmine Paolino</name></author><category term="Solco" /><category term="DJing" /><category term="AI" /><category term="Rust" /><summary type="html"><![CDATA[Solco grids, keys and characterises your whole DJ library on your computer and writes the USB your CDJs read. It's in private beta: join the waitlist for a personal licence key.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://paolino.me/images/solco.jpg" /><media:content medium="image" url="https://paolino.me/images/solco.jpg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">I Get 215 GitHub Notifications a Day, So I Built a Bot to Triage Them</title><link href="https://paolino.me/copilot-triage/" rel="alternate" type="text/html" title="I Get 215 GitHub Notifications a Day, So I Built a Bot to Triage Them" /><published>2026-10-23T00:00:00+00:00</published><updated>2026-10-23T10:28:32+00:00</updated><id>https://paolino.me/copilot-triage</id><content type="html" xml:base="https://paolino.me/copilot-triage/"><![CDATA[<p>When your open source project gets popular, the real work starts.</p>

<p>I counted everything that happened in my repositories in the last 30 days, leaving out what I did myself:</p>

<ul>
  <li><strong>42 new issues and pull requests a day</strong> from people. <a href="https://github.com/crmne/spotifast">Spotifast</a> and <a href="https://github.com/crmne/zapfast">ZapFast</a>, both two months old, brought in about 430 each. <a href="https://github.com/crmne/ruby_llm">RubyLLM</a> brought in about 270.</li>
  <li><strong>49 comments and review comments a day</strong> from people.</li>
  <li><strong>About 125 comments a day from review bots.</strong> <a href="https://www.coderabbit.ai">CodeRabbit</a> alone left 2,669 review comments, and <a href="https://docs.github.com/en/copilot/how-tos/use-copilot-agents/request-a-code-review/use-code-review">Copilot code review</a> another 974.</li>
</ul>

<p>That’s about 215 notifications a day, every day, on top of building the things people are filing issues about. Each one is an email, a badge on the bell, a push on my phone. I can’t read all of them, and the important ones get buried under the rest: a pull request waiting for my sign-off ends up under fifty comments about a bug that was fixed last week.</p>

<p>So I built <a href="https://github.com/crmne/copilot-triage">Copilot Triage</a>. It reads every issue, discussion, and pull request, answers the reporter when it has something useful to say, and puts everything on a board sorted by what it needs from me. I turned off GitHub’s email and open the board, a <a href="https://docs.github.com/en/issues/planning-and-tracking-with-projects">GitHub Project</a>, instead.</p>

<p>It’s an independent open source project, not made by GitHub. The name comes from what it runs on: your <a href="https://github.com/features/copilot">GitHub Copilot</a> allowance by default, or any model through <a href="https://rubyllm.com">RubyLLM</a>.</p>

<h2 id="the-board">The board</h2>

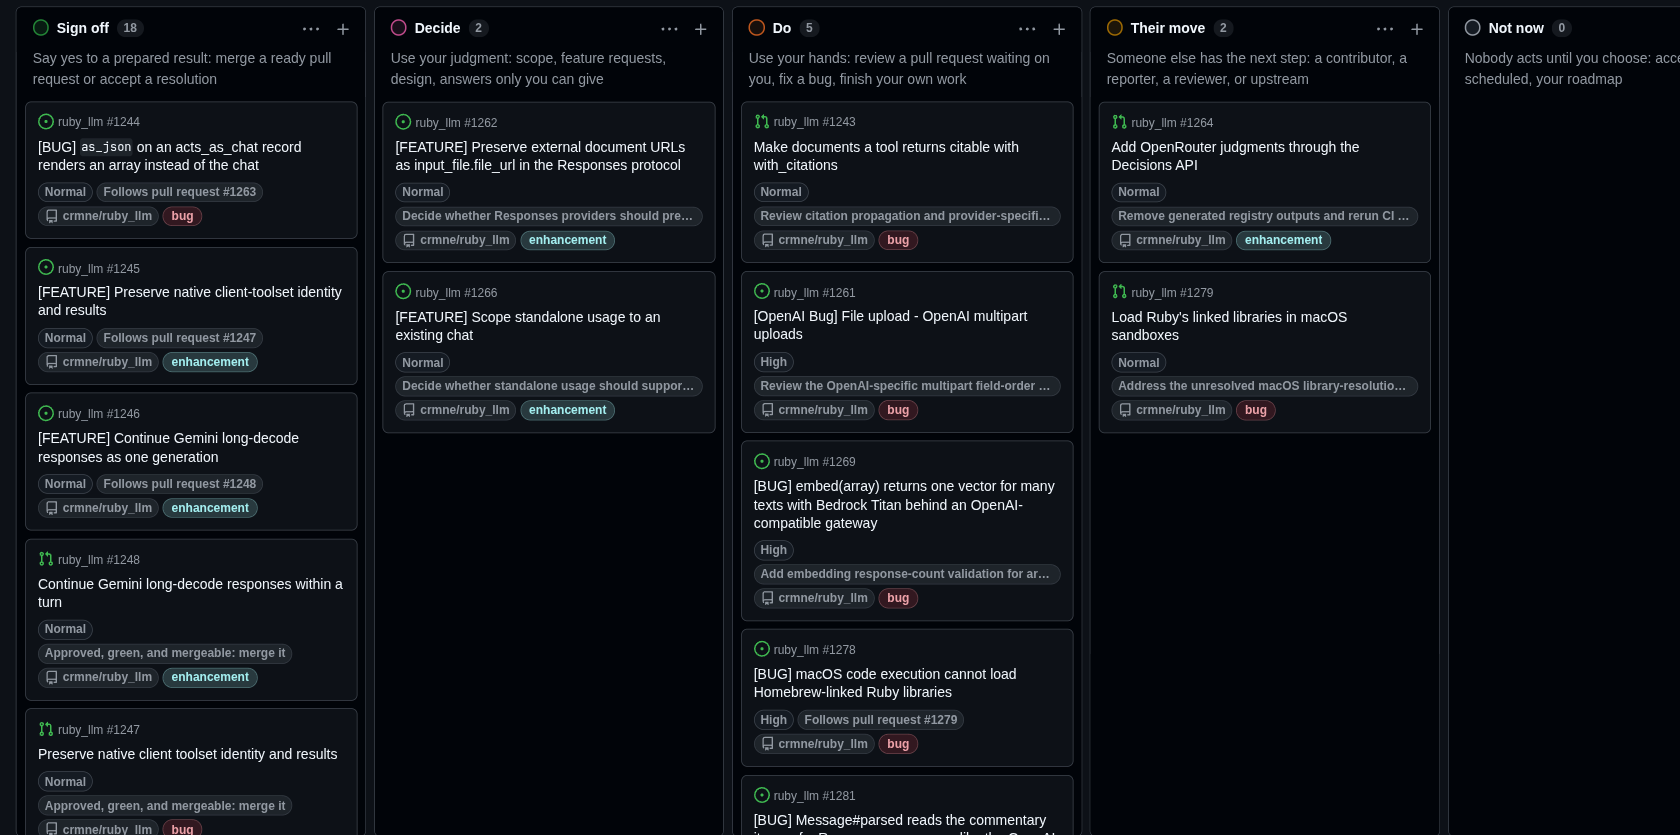
<p><img src="/images/copilot-triage-board.png" alt="The Maintainer board for RubyLLM: Sign off, Decide, Do, Their move and Not now columns, each card with a priority and a next step." width="1680" height="835" loading="lazy" decoding="async" /></p>

<p>Every issue and pull request lands on the board, in the column for what it needs from me:</p>

<ul>
  <li><strong>Sign off</strong>: pull requests that were reviewed and are ready for me to merge.</li>
  <li><strong>Decide</strong>: questions only I can answer, such as whether a feature fits.</li>
  <li><strong>Do</strong>: work that’s mine, like a confirmed bug or a pull request nobody has reviewed yet.</li>
  <li><strong>Their move</strong>: waiting on the reporter or the contributor.</li>
</ul>

<p>Each card has a priority and a one-line next step, so I know what to do before I open it. Urgent issues get assigned to me, and my review is requested on the pull requests that need it.</p>

<h2 id="what-it-does-with-each-report">What it does with each report</h2>

<p>When someone opens an issue, the agent investigates with six read-only tools:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">search_repository</code> finds literal matches in the docs and source paths you configure.</li>
  <li><code class="language-plaintext highlighter-rouge">search_issues</code> looks for earlier issues about the same problem.</li>
  <li><code class="language-plaintext highlighter-rouge">list_releases</code> lists recent releases with their notes.</li>
  <li><code class="language-plaintext highlighter-rouge">search_changes</code> searches release notes and unreleased commits for a phrase, to tell whether a fix already shipped or is still on the main branch.</li>
  <li><code class="language-plaintext highlighter-rouge">read_evidence</code> opens a file, issue, release, or pull request diff that one of the searches turned up.</li>
  <li><code class="language-plaintext highlighter-rouge">submit_decision</code> hands over its decision: labels, an optional reply, and the next step for the card on the board.</li>
</ul>

<p>It picks which tools to use and in what order, and then decides what would help. Usually that’s a label and nothing else. When it can help, it posts one reply: the answer from the docs, the release that fixed it, the existing issue it duplicates, the one question the report is missing, or a short summary of a long report.</p>

<p>Discussions get answered from the docs, and a discussion that’s really a bug report moves to an issue. For pull requests, it requests a <a href="https://docs.github.com/en/copilot/how-tos/use-copilot-agents/request-a-code-review/use-code-review">Copilot code review</a> when a change deserves one, reads the verdict when it arrives, and checks the contribution guidelines, like opening an issue first or attaching screenshots for UI changes. Merging is always up to me.</p>

<h2 id="one-agent-instead-of-2035-lines-of-yaml">One agent instead of 2,035 lines of YAML</h2>

<p>My first attempt used <a href="https://github.com/github/gh-aw">GitHub Agentic Workflows</a>. For RubyLLM, the <a href="https://github.com/crmne/ruby_llm/blob/d04b4eeb341d76440bee9a029f150b7598e5cfcc/.github/workflows/issue-assessment.lock.yml">compiled workflow</a> was 2,035 lines of YAML: tool gateways, agent jobs, a threat detector, safe-output jobs, and failure reporting. Then it started <a href="https://github.com/crmne/ruby_llm/issues/922">opening issues about its own failures</a> and <a href="https://github.com/crmne/ruby_llm/issues/913">commenting about its detector failing</a>, which was more email, not less.</p>

<p>The first versions of Copilot Triage went the other way: short, bounded prompts, separate routes for answering from files, looking things up, and comparing duplicates, and keyword ranking and regex rules guessing whether a follow-up mattered. Every new kind of report needed another route. In <a href="https://github.com/crmne/copilot-triage/releases/tag/v0.6.0">0.6</a> I replaced all of that with one agent that chooses its own searches. Copilot Triage is now a <a href="https://rubyllm.com">RubyLLM</a> agent with a system prompt and the six tools above:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">class</span> <span class="nc">TriageAgent</span> <span class="o">&lt;</span> <span class="no">RubyLLM</span><span class="o">::</span><span class="no">Agent</span>
  <span class="n">instructions</span> <span class="p">{</span> <span class="n">system_prompt</span> <span class="p">}</span>
  <span class="n">tools</span> <span class="k">do</span>
    <span class="p">[</span><span class="no">SearchRepository</span><span class="p">,</span> <span class="no">SearchIssues</span><span class="p">,</span> <span class="no">ListReleases</span><span class="p">,</span> <span class="no">SearchChanges</span><span class="p">,</span> <span class="no">ReadEvidence</span><span class="p">,</span> <span class="no">SubmitDecision</span><span class="p">]</span>
      <span class="p">.</span><span class="nf">map</span> <span class="p">{</span> <span class="o">|</span><span class="n">tool</span><span class="o">|</span> <span class="n">tool</span><span class="p">.</span><span class="nf">new</span><span class="p">(</span><span class="n">toolbox</span><span class="p">)</span> <span class="p">}</span>
  <span class="k">end</span>
<span class="k">end</span>
</code></pre></div></div>

<p>The agent picks what to search and reads what it finds, with a budget of 12 searches and reads per report. Its last call submits a decision. The model can’t change anything on GitHub: there’s no shell, no file access, and no tool that writes. Ruby checks the decision, re-reads the report, verifies the evidence the model cited, and only then labels, comments, closes, or moves the card. If the report changed while the agent was working, it’s left alone.</p>

<p>When something goes wrong, the error goes to the <a href="https://github.com/features/actions">GitHub Actions</a> job summary. It doesn’t open an issue about it.</p>

<h2 id="it-used-to-reply-too-much">It used to reply too much</h2>

<p>Before <a href="https://github.com/crmne/copilot-triage/releases/tag/v0.18.0">0.18</a> I went through everything triage did across my repositories in one week. Labels were right 95% of the time. Replies were much worse: only a third of them actually helped anyone. The rest were things like “Thanks for the report!”, a second and third diagnostic question after the reporter had already answered the first, or a link to an issue that was already linked in the thread.</p>

<p>Each of those replies is another notification, for the reporter and for me. A wrong label costs me a click to fix, but a wrong reply costs the reporter’s time and some goodwill toward the project. A triage bot that adds noise defeats the point.</p>

<p>So it now replies much less. A thank-you gets no answer. When a reporter answers its question, it doesn’t ask another one unless the answer reveals something new. After I comment, it replies at most twice more, then stops and moves the card to Decide. A clear report gets labels and no comment.</p>

<p>Changing a prompt to make a bot quieter is easy. Knowing it still answers when it should is the hard part, and for that I needed evaluations.</p>

<h2 id="evaluations">Evaluations</h2>

<p>The evaluation is a <a href="https://rubyllm.com"><code class="language-plaintext highlighter-rouge">RubyLLM::Evaluation</code></a> with 32 cases. Most are modeled on real reports from my repositories, and each one says what should happen:</p>

<ul>
  <li><strong>Silence</strong>: a reporter asking the bot to stop (<a href="https://github.com/crmne/zapfast/issues/20">ZapFast #20</a>), a thank-you, repeated measurements, a question that was already answered, a clear feature request.</li>
  <li><strong>Help</strong>: an answer that’s in the docs, a fix that already shipped, a missing error message that’s essential, a recap of a long report.</li>
  <li><strong>Duplicates</strong>: a real one, and a look-alike that isn’t (<a href="https://github.com/crmne/spotifast/issues/821">Spotifast #821</a>).</li>
  <li><strong>Traps</strong>: a feature that’s documented on the main branch but not released yet (<a href="https://github.com/crmne/zapfast/issues/508">ZapFast #508</a>). The reply has to say it’s coming, not that it already exists.</li>
</ul>

<p>A case passes only with the expected action, the text the reply must contain (and none it must not), at least the evidence reads it needs, and no more model calls than its budget.</p>

<p>It runs in two modes. Offline, it replays recorded tool calls and decisions through the real tools and publisher against fixture GitHub data. That costs nothing, runs on every change, and catches plumbing bugs, but it can’t tell me whether a model behaves. Live, the real model investigates the same fixtures, with publishing switched to dry run. I run that before every release and before changing the default model. Because the evaluation also shows up in the RSpec suite, each case fails like an ordinary test.</p>

<p>The last full comparison ran each case twice:</p>

<table>
  <thead>
    <tr>
      <th>Model</th>
      <th>Passed</th>
      <th>Unneeded replies</th>
      <th>Missed help</th>
      <th>Cost per assessment</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>GPT-5.6 Luna (default)</td>
      <td>29/30</td>
      <td>0</td>
      <td>1</td>
      <td>$0.0039</td>
    </tr>
    <tr>
      <td>GPT-6 Luna</td>
      <td>23/30</td>
      <td>3</td>
      <td>2</td>
      <td>$0.0023</td>
    </tr>
    <tr>
      <td>Claude Haiku 4.5</td>
      <td>19/30</td>
      <td>1</td>
      <td>10</td>
      <td>$0.0228</td>
    </tr>
    <tr>
      <td>GPT-5 mini</td>
      <td>8/30</td>
      <td>9</td>
      <td>0</td>
      <td>$0.0087</td>
    </tr>
  </tbody>
</table>

<p>GPT-5 mini replies to almost everything. Claude Haiku stays quiet even when the docs have the answer. GPT-6 Luna is newer and cheaper, but misses more and replies more when it shouldn’t, so newer isn’t automatically better for a job like this. Gemini 3.6 Flash never finished a case within Copilot’s 90-second limit, and small local models failed most cases even with the same tools. You can run it against any model:</p>

<div class="language-sh highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nv">EVAL_LIVE</span><span class="o">=</span><span class="nb">true </span><span class="nv">TRIAGE_MODEL</span><span class="o">=</span>gpt-5.6-luna bundle <span class="nb">exec </span>rake ruby_llm:eval
</code></pre></div></div>

<h2 id="33-releases-in-five-weeks">33 releases in five weeks</h2>

<p>I released <a href="https://github.com/crmne/copilot-triage/releases">33 versions</a> between September 15 and October 17, almost all of them tuning. Running it on busy repositories found problems no evaluation had, and many of those reports became evaluation cases. Some of what I learned:</p>

<ul>
  <li><strong>Docs on the main branch aren’t what users have.</strong> It read the docs from the default branch, so it told people a feature already existed when it was only on <code class="language-plaintext highlighter-rouge">main</code>. Now every file it reads says how many commits it is past the last release.</li>
  <li><strong>Review bots catch different things.</strong> I classified 693 findings from Copilot and CodeRabbit across 196 pull requests. The two found different problems, and Copilot found little that mattered on small changes, so triage now asks Copilot for a review only on changes where it pays off.</li>
  <li><strong>“Reviewed” needs checking.</strong> CodeRabbit silently stopped reviewing after hitting its limit, and dozens of pull requests ended up in Sign off without anyone having read them. Now a pull request only reaches Sign off once something reviewed its latest commit.</li>
  <li><strong>Agent sessions sometimes end without doing anything.</strong> About one in five Copilot sessions finished without a single tool call, mostly when many pull requests opened at once. Those runs now retry.</li>
  <li><strong>Fallbacks have to do the whole job.</strong> When the Copilot allowance ran out, the fallback model placed cards but posted nothing, so every report filed after that went unanswered.</li>
  <li><strong>Your platform can change under you.</strong> GitHub made the Actions cache read-only for issue and comment events, so for a while the bot forgot muted threads and its own earlier replies.</li>
</ul>

<h2 id="cost">Cost</h2>

<p>By default it runs on your Copilot allowance, at about a cent or less per report at <a href="https://docs.github.com/en/copilot/reference/copilot-billing/models-and-pricing">GitHub’s listed prices</a>. When the allowance runs out, it can switch to an API key and keep going.</p>

<p>You can also skip Copilot and set <code class="language-plaintext highlighter-rouge">engine: rubyllm</code> to run the same agent on any provider RubyLLM supports: your company’s <a href="https://platform.openai.com">OpenAI</a> or <a href="https://www.anthropic.com/api">Anthropic</a> key, <a href="https://openrouter.ai">OpenRouter</a>, <a href="https://aws.amazon.com/bedrock/">Amazon Bedrock</a>, <a href="https://azure.microsoft.com/en-us/products/ai-foundry">Azure</a>, or a local model on <a href="https://ollama.com">Ollama</a>.</p>

<h2 id="building-bots-like-this-in-chat-with-work">Building bots like this in Chat with Work</h2>

<p>I also make <a href="https://chatwithwork.com">Chat with Work</a>, an AI agent for work, and you can build bots like this one there without writing code. A Chat with Work bot can start when an issue or pull request is opened, commented on, or labeled, and keep one conversation going per issue. Once an admin installs its <a href="https://chatwithwork.com/integrations/github">GitHub App</a> on your repositories, it reads the issue and the repository’s code, then labels, comments, or closes. You decide which of those it does on its own and which wait for your approval. The <a href="https://chatwithwork.com/recipes/github-issue-triage">issue triage recipe</a> sets it up in a few clicks. It can also open draft pull requests with fixes, and the same bots can run on schedules, emails, Slack messages, and more.</p>

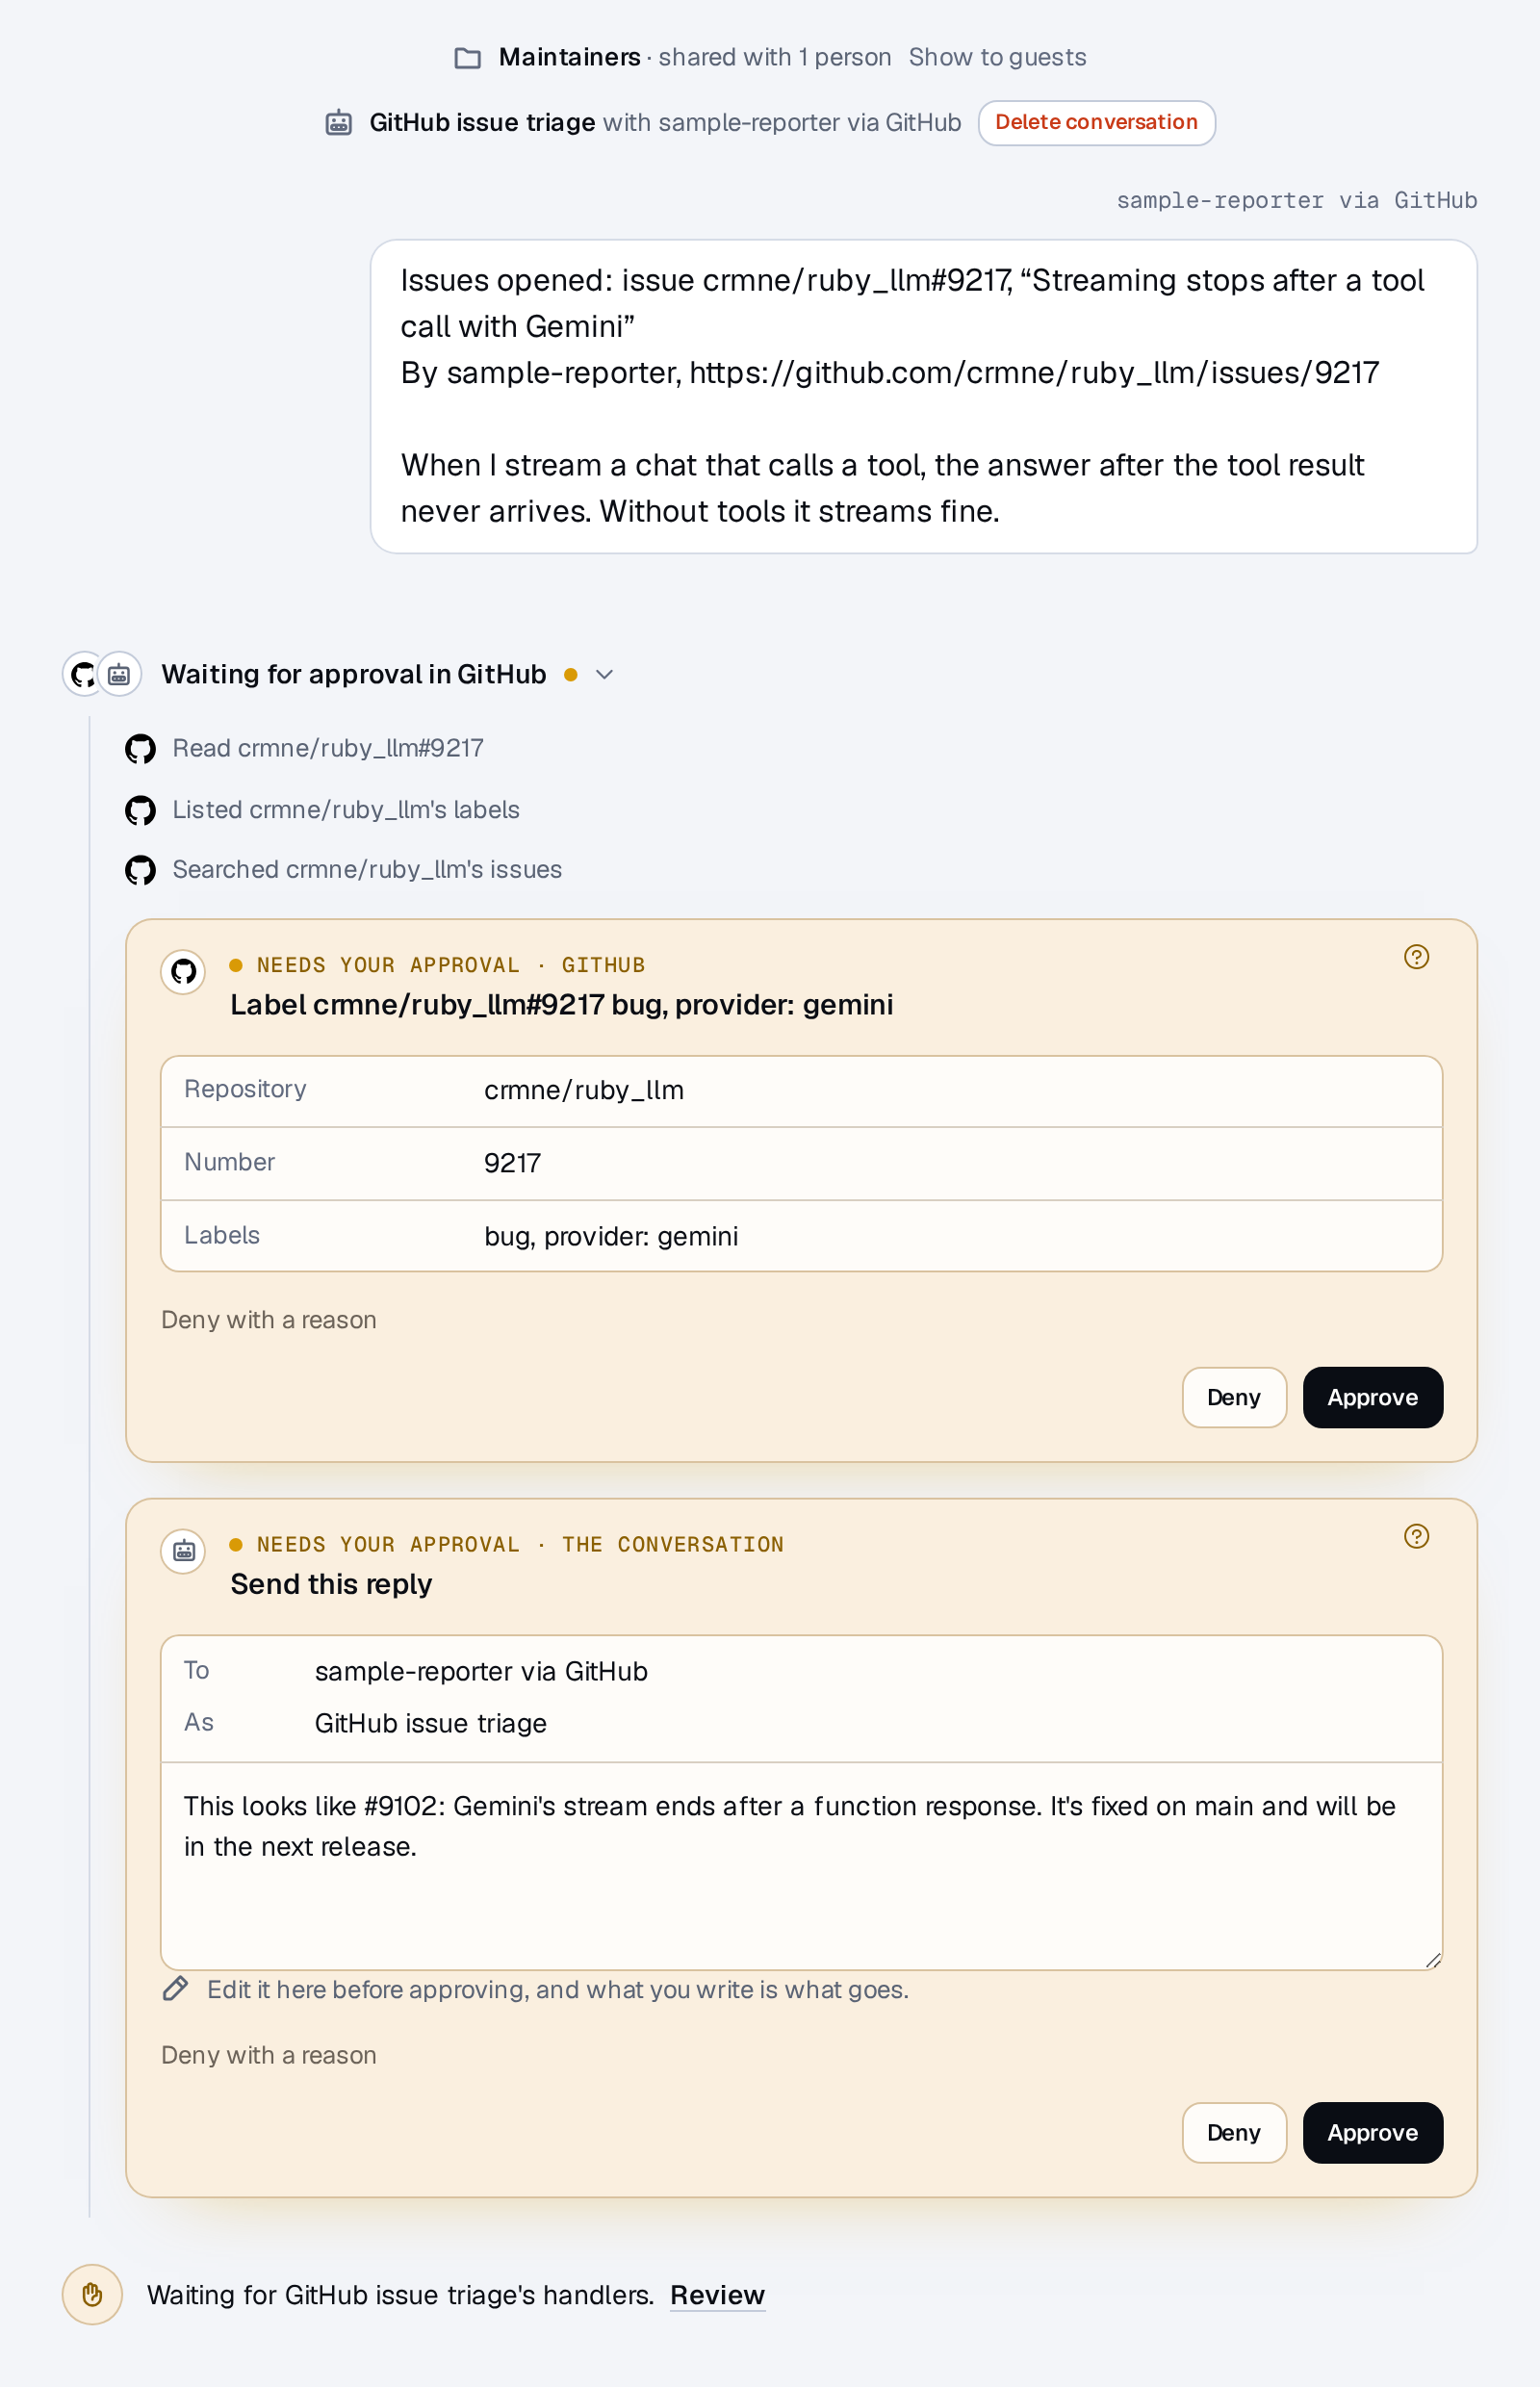
<p>Here’s the triage bot on an example issue, set to ask first for everything: it read the issue, checked the labels, searched for duplicates, and is waiting for me to approve the labels and its reply.</p>

<p><img src="/images/chat-with-work-triage-bot.png" alt="A Chat with Work triage bot on an example RubyLLM issue: it read the issue, listed labels, and searched issues, and two approval cards wait, one to label the issue bug and provider: gemini, one to send a reply pointing to the duplicate issue that is fixed on main." width="1600" height="2480" loading="lazy" decoding="async" style="max-width: 640px; width: 100%; height: auto; display: block; margin: 0 auto;" /></p>

<h2 id="try-it">Try it</h2>

<p>It’s a <a href="https://github.com/marketplace/actions/copilot-triage">GitHub Action</a>. You need a token, a <code class="language-plaintext highlighter-rouge">triage.yml</code> file with your labels and project rules, and a short workflow file. It runs on all my repositories, from <a href="https://github.com/crmne/ruby_llm">RubyLLM</a> to <a href="https://github.com/crmne/spotifast">Spotifast</a>.</p>

<p><a href="https://github.com/crmne/copilot-triage">Copilot Triage on GitHub</a></p>]]></content><author><name>Carmine Paolino</name></author><category term="Ruby" /><category term="RubyLLM" /><category term="AI" /><category term="Agents" /><category term="GitHub" /><category term="Open Source" /><category term="Copilot Triage" /><summary type="html"><![CDATA[My repositories send me about 215 GitHub notifications a day. Copilot Triage reads them, answers reporters when it can help, and sorts everything that needs me into one board.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://paolino.me/images/copilot-triage.png" /><media:content medium="image" url="https://paolino.me/images/copilot-triage.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">RubyLLM 2.1: You Can Have It All</title><link href="https://paolino.me/rubyllm-2-1/" rel="alternate" type="text/html" title="RubyLLM 2.1: You Can Have It All" /><published>2026-10-08T09:10:00+00:00</published><updated>2026-10-14T14:33:02+00:00</updated><id>https://paolino.me/rubyllm-2-1</id><content type="html" xml:base="https://paolino.me/rubyllm-2-1/"><![CDATA[<p><a href="https://rubyllm.com">RubyLLM</a> 2.1 is out. I released it on stage at Deccan Queen on Rails in Pune.</p>

<p>With 2.1, RubyLLM does everything LangChain, LangGraph, and LangSmith do together, apart from two things it leaves out on purpose. Several things those frameworks leave to you or to their paid platform, such as per-user MCP OAuth, cancelling a run from another process, and provider batch APIs, are built in. <a href="#compared">The comparison</a> has the details.</p>

<p>There’s also a <a href="https://github.com/crmne/ruby_llm/releases/download/v2.1.0/rubyllm-tour.mp4">three-minute tour of 2.1</a>.</p>

<p>It builds on <a href="/rubyllm-2-0/">2.0</a> and adds an MCP client, tool search, typed judgments, evaluations, tool progress, OpenTelemetry tracing, and a nineteenth provider. It’s also faster, with no code changes. In this post:</p>

<ul>
  <li><a href="#compared">Compared with LangChain, LangGraph, and LangSmith</a></li>
  <li><a href="#mcp">MCP client</a></li>
  <li><a href="#tool-search">Tool search</a></li>
  <li><a href="#judgments">Judgments</a></li>
  <li><a href="#evaluations">Evaluations</a></li>
  <li><a href="#faster">Faster by default</a></li>
  <li><a href="#tool-progress">Tool progress</a></li>
  <li><a href="#opentelemetry">OpenTelemetry</a></li>
  <li><a href="#smaller-changes">Smaller changes</a></li>
  <li><a href="#upgrading">Upgrading from 2.0</a></li>
</ul>

<h2 id="compared">Compared with LangChain, LangGraph, and LangSmith</h2>

<p>RubyLLM 2.1 next to the three Python frameworks combined:</p>

<table>
  <thead>
    <tr>
      <th> </th>
      <th>RubyLLM 2.1</th>
      <th>LangChain + LangGraph + LangSmith</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Chat, streaming, tools, structured output</td>
      <td>✓</td>
      <td>✓</td>
    </tr>
    <tr>
      <td>Images, PDFs, audio as input</td>
      <td>✓</td>
      <td>✓</td>
    </tr>
    <tr>
      <td>Embeddings, reranking</td>
      <td>✓</td>
      <td>✓</td>
    </tr>
    <tr>
      <td>Image, video, speech, transcription, and OCR in one API</td>
      <td>✓</td>
      <td>Partial: one vendor tool per service</td>
    </tr>
    <tr>
      <td>Agents and the agentic loop</td>
      <td>✓</td>
      <td>✓</td>
    </tr>
    <tr>
      <td>MCP client</td>
      <td>✓</td>
      <td>✓</td>
    </tr>
    <tr>
      <td>Per-user MCP OAuth on a server</td>
      <td>✓</td>
      <td>Partial: you supply each user’s token</td>
    </tr>
    <tr>
      <td>Tool search</td>
      <td>✓</td>
      <td>✓</td>
    </tr>
    <tr>
      <td>Approvals that survive a deploy</td>
      <td>✓</td>
      <td>✓</td>
    </tr>
    <tr>
      <td>Cancel a run from another process</td>
      <td>✓</td>
      <td>Paid platform (LangSmith Deployment)</td>
    </tr>
    <tr>
      <td>Cost per attempt, in your database</td>
      <td>✓</td>
      <td>Build it yourself (costs live in LangSmith)</td>
    </tr>
    <tr>
      <td>Evaluations, local and in CI</td>
      <td>✓</td>
      <td>✓</td>
    </tr>
    <tr>
      <td>Judgment models (Jev, Clef)</td>
      <td>✓</td>
      <td>Build it yourself</td>
    </tr>
    <tr>
      <td>OpenTelemetry</td>
      <td>✓</td>
      <td>✓</td>
    </tr>
    <tr>
      <td>Prompt caching, fallbacks</td>
      <td>✓</td>
      <td>✓</td>
    </tr>
    <tr>
      <td>Provider batch APIs</td>
      <td>✓</td>
      <td>Build it yourself (<code class="language-plaintext highlighter-rouge">.batch()</code> runs requests in parallel, at full price)</td>
    </tr>
    <tr>
      <td>MCP servers</td>
      <td>Left out on purpose</td>
      <td>Paid platform (Agent Server)</td>
    </tr>
    <tr>
      <td>Vector stores</td>
      <td>Left out on purpose</td>
      <td>✓</td>
    </tr>
  </tbody>
</table>

<p>The LangChain column comes from <a href="https://docs.langchain.com">their documentation</a>. They have more integrations. RubyLLM has one API across nineteen providers, and it fits into Rails: approvals are a controller action and a job, evaluations live in <code class="language-plaintext highlighter-rouge">app/evals</code>, and costs are rows in your database.</p>

<p>The two rows left out belong elsewhere. An MCP server is part of your application, so use the <a href="https://github.com/modelcontextprotocol/ruby-sdk">mcp gem</a> or <a href="https://github.com/yjacquin/fast-mcp">fast-mcp</a>. For vector search, <a href="https://github.com/ankane/neighbor">neighbor</a> and pgvector already do it well.</p>

<h2 id="mcp">An MCP Client Where You Decide What the Model Sees</h2>

<p>In RubyLLM 2.1 an MCP server is a Ruby class you own: it lives in your repo, and it says exactly which tools the model gets.</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">class</span> <span class="nc">Linear</span> <span class="o">&lt;</span> <span class="no">RubyLLM</span><span class="o">::</span><span class="no">MCP</span>
  <span class="n">url</span> <span class="s2">"https://mcp.linear.app/mcp"</span>
  <span class="n">inputs</span> <span class="ss">:user</span>
  <span class="n">oauth</span> <span class="ss">owner: :user</span>

  <span class="n">only</span> <span class="ss">:list_issues</span><span class="p">,</span> <span class="ss">:get_issue</span><span class="p">,</span> <span class="ss">:create_issue</span> <span class="c1"># the model sees these three</span>
  <span class="n">requires_approval</span> <span class="ss">:create_issue</span>
<span class="k">end</span>

<span class="n">chat</span> <span class="o">=</span> <span class="no">RubyLLM</span><span class="p">.</span><span class="nf">chat</span><span class="p">.</span><span class="nf">with_mcp</span><span class="p">(</span><span class="no">Linear</span><span class="p">.</span><span class="nf">new</span><span class="p">(</span><span class="ss">user: </span><span class="n">current_user</span><span class="p">))</span> <span class="c1"># one connection per user</span>
<span class="n">chat</span><span class="p">.</span><span class="nf">ask</span> <span class="s2">"What's blocking the release?"</span>
</code></pre></div></div>

<p>Each user signs in to the server with their own account. RubyLLM handles OAuth discovery, registration, PKCE, and refresh, and stores each user’s credentials encrypted with Active Record encryption. MCP tools that <code class="language-plaintext highlighter-rouge">requires_approval</code> use the same approval flow as your own tools, so in Rails the job finishes and another one continues after the user approves. The client follows the MCP 2026-07-28 specification, and the official conformance suite runs in CI.</p>

<p>To try a server before shaping it, connect from the console. Every tool becomes a Ruby method:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="o">&gt;&gt;</span> <span class="n">docs</span> <span class="o">=</span> <span class="no">RubyLLM</span><span class="p">.</span><span class="nf">mcp</span><span class="p">(</span><span class="ss">url: </span><span class="s2">"https://learn.microsoft.com/api/mcp"</span><span class="p">)</span>
<span class="o">&gt;&gt;</span> <span class="n">docs</span><span class="p">.</span><span class="nf">microsoft_docs_search</span><span class="p">(</span><span class="ss">query: </span><span class="s2">"Azure Blob Storage"</span><span class="p">).</span><span class="nf">text</span>
<span class="o">=&gt;</span> <span class="s2">"..."</span>
</code></pre></div></div>

<p>The same class can rename tools, rewrite their descriptions, fix arguments, and wrap results, which is how 2.1 follows the advice from April that your agent’s <a href="/your-agents-context-window-is-not-a-junk-drawer/">context window is not a junk drawer</a>: prototype with MCP, then craft the tools you control. Before this, <a href="https://github.com/patvice/ruby_llm-mcp">ruby_llm-mcp</a> by @patvice carried MCP for RubyLLM users for a long time. Thank you. If you use it, remove it before updating, since it defines the same <code class="language-plaintext highlighter-rouge">RubyLLM::MCP</code> constant. With MCP Apps, a server ships its own interface, such as a chart or a form, and RubyLLM hands it to your app to show next to the tool’s results. The <a href="https://rubyllm.com/mcp/">MCP Client guide</a> covers OAuth, input requests, resources, prompts, MCP Apps, and Tasks.</p>

<h2 id="tool-search">Tool Search</h2>

<p>A few MCP servers can put hundreds of tool definitions in front of the model on every turn. Defer them, and the model searches for the tools it needs instead:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">chat</span><span class="p">.</span><span class="nf">with_mcp</span><span class="p">(</span><span class="no">GitHub</span><span class="p">.</span><span class="nf">new</span><span class="p">(</span><span class="ss">user: </span><span class="n">current_user</span><span class="p">),</span> <span class="no">Linear</span><span class="p">.</span><span class="nf">new</span><span class="p">(</span><span class="ss">user: </span><span class="n">current_user</span><span class="p">),</span> <span class="ss">defer: </span><span class="kp">true</span><span class="p">)</span> <span class="c1"># tools stay out of the context</span>
<span class="n">chat</span><span class="p">.</span><span class="nf">ask</span> <span class="s2">"Which open issues mention the flaky login spec?"</span>
</code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">with_tools</code> and agents take the same <code class="language-plaintext highlighter-rouge">defer:</code> option. Anthropic and OpenAI’s Responses API search natively, and other providers receive deferred tools as ordinary tools, so the same code runs everywhere. See <a href="https://rubyllm.com/tool-search/">Tool Search</a>.</p>

<h2 id="judgments">Judgments</h2>

<p>Judgments answer questions about your own data (is this urgent, which team owns it) with probabilities a model measured, instead of a confidence number it wrote as text:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">class</span> <span class="nc">TicketTriage</span> <span class="o">&lt;</span> <span class="no">RubyLLM</span><span class="o">::</span><span class="no">Judge</span>
  <span class="n">probability</span> <span class="ss">:urgent</span><span class="p">,</span> <span class="s2">"Does this need attention today?"</span>

  <span class="n">choice</span> <span class="ss">:department</span><span class="p">,</span> <span class="s2">"Which team should handle this?"</span> <span class="k">do</span>
    <span class="n">billing</span>   <span class="s2">"Payments and refunds"</span>
    <span class="n">technical</span> <span class="s2">"Bugs and integrations"</span>
    <span class="n">other</span>     <span class="s2">"Everything else"</span>
  <span class="k">end</span>

  <span class="n">score</span> <span class="ss">:frustration</span><span class="p">,</span> <span class="s2">"How frustrated is the customer?"</span><span class="p">,</span>
    <span class="p">[</span><span class="s2">"Calm"</span><span class="p">,</span> <span class="s2">"Frustrated"</span><span class="p">,</span> <span class="s2">"Angry"</span><span class="p">]</span>
<span class="k">end</span>

<span class="n">judgment</span> <span class="o">=</span> <span class="no">TicketTriage</span><span class="p">.</span><span class="nf">judge</span><span class="p">(</span><span class="s2">"Please refund the duplicate charge today."</span><span class="p">)</span>
<span class="n">judgment</span><span class="p">.</span><span class="nf">urgent</span><span class="p">.</span><span class="nf">probability</span> <span class="c1"># =&gt; 0.96</span>
<span class="n">judgment</span><span class="p">.</span><span class="nf">department</span><span class="p">.</span><span class="nf">choice</span>  <span class="c1"># =&gt; :billing</span>
</code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">probability</code>, <code class="language-plaintext highlighter-rouge">choice</code>, and <code class="language-plaintext highlighter-rouge">score</code> questions are all asked over the same input in one request, and your code acts on them with thresholds you pick. Judges default to Jev models from TypeSafe, a new built-in provider. Kieran Klaassen added OpenAI’s <code class="language-plaintext highlighter-rouge">gpt-6-luna</code> through the Decisions API (<a href="https://github.com/crmne/ruby_llm/pull/1008">#1008</a>). To judge on your own machine, run Cloudflare’s Clef through Ollama. See the <a href="https://rubyllm.com/judgments/">Judgments guide</a>.</p>

<h2 id="evaluations">Evaluations</h2>

<p>An evaluation runs your agent on cases with known answers and has a model grade each response, so you can tell whether a prompt or model change made things better. Cases live in a YAML file next to the class, and <code class="language-plaintext highlighter-rouge">bin/rails "ruby_llm:eval[DocsEvaluation]"</code> runs them and exits non-zero on failure, so it works in CI:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">class</span> <span class="nc">DocsEvaluation</span> <span class="o">&lt;</span> <span class="no">RubyLLM</span><span class="o">::</span><span class="no">Evaluation</span>
  <span class="n">evaluation</span> <span class="ss">:correctness</span> <span class="c1"># keeps the default check</span>
  <span class="n">evaluation</span> <span class="ss">:grounded</span><span class="p">,</span> <span class="s2">"Every claim is supported by the documents in metadata"</span>
  <span class="n">evaluation</span> <span class="ss">:cites_sources</span><span class="p">,</span> <span class="s2">"The answer links to at least one document"</span>

  <span class="k">def</span> <span class="nf">perform</span><span class="p">(</span><span class="n">question</span><span class="p">)</span>
    <span class="no">DocsAgent</span><span class="p">.</span><span class="nf">new</span><span class="p">.</span><span class="nf">ask</span><span class="p">(</span><span class="n">question</span><span class="p">)</span>
  <span class="k">end</span>
<span class="k">end</span>
</code></pre></div></div>

<p>Evaluations can also grade tool calls with plain Ruby assertions, use an Agent or a Judge as the grader, and run as RSpec or Minitest tests. See the <a href="https://rubyllm.com/evaluations/">Evaluations guide</a>.</p>

<h2 id="faster">Faster by Default</h2>

<p>2.1 does less work on every call, with no code changes. RubyLLM’s own work, 2.0.0 against 2.1 on the same machine:</p>

<table>
  <thead>
    <tr>
      <th>Workload</th>
      <th>2.0</th>
      <th>2.1</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Stream a 2 MB event that arrives in 16 KB pieces</td>
      <td>116 ms</td>
      <td>2.0 ms</td>
    </tr>
    <tr>
      <td>Stream 500 Perplexity chunks that each cite 20 sources</td>
      <td>137 ms</td>
      <td>17 ms</td>
    </tr>
    <tr>
      <td>Ask a Bedrock chat with 200 messages of history</td>
      <td>2.9 ms</td>
      <td>0.40 ms</td>
    </tr>
    <tr>
      <td>Memory kept by a streamed 40-turn chat with a 256 KB image</td>
      <td>28 MB</td>
      <td>0.48 MB</td>
    </tr>
    <tr>
      <td>Eight threads loading the model registry at once</td>
      <td>273 ms</td>
      <td>32 ms</td>
    </tr>
  </tbody>
</table>

<p>Connections are now shared across calls, threads, and fibers. To keep them open, pick a persistent adapter (from the <code class="language-plaintext highlighter-rouge">faraday-net_http_persistent</code> gem):</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">config</span><span class="p">.</span><span class="nf">faraday_adapter</span> <span class="o">=</span> <span class="ss">:net_http_persistent</span> <span class="c1"># keeps connections open</span>
</code></pre></div></div>

<p>The benchmarks need no API keys: clone RubyLLM and run <code class="language-plaintext highlighter-rouge">bundle exec rake "benchmark:compare[v2.0.0]"</code> to compare any version with your checkout. The <a href="https://rubyllm.com/configuration-connection/#connection-reuse">connection guide</a> covers adapters.</p>

<h2 id="tool-progress">Tools That Report Progress</h2>

<p>A slow tool can now tell your user what it’s doing instead of leaving them with a spinner:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">class</span> <span class="nc">ReadReport</span> <span class="o">&lt;</span> <span class="no">RubyLLM</span><span class="o">::</span><span class="no">Tool</span>
  <span class="k">def</span> <span class="nf">execute</span><span class="p">(</span><span class="n">url</span><span class="p">:)</span>
    <span class="n">pages</span> <span class="o">=</span> <span class="no">Scanner</span><span class="p">.</span><span class="nf">pages</span><span class="p">(</span><span class="n">url</span><span class="p">)</span>
    <span class="n">pages</span><span class="p">.</span><span class="nf">each_with_index</span><span class="p">.</span><span class="nf">map</span> <span class="k">do</span> <span class="o">|</span><span class="n">page</span><span class="p">,</span> <span class="n">index</span><span class="o">|</span>
      <span class="n">progress</span> <span class="s2">"Reading page </span><span class="si">#{</span><span class="n">index</span> <span class="o">+</span> <span class="mi">1</span><span class="si">}</span><span class="s2"> of </span><span class="si">#{</span><span class="n">pages</span><span class="p">.</span><span class="nf">size</span><span class="si">}</span><span class="s2">"</span><span class="p">,</span> <span class="ss">value: </span><span class="n">index</span> <span class="o">+</span> <span class="mi">1</span><span class="p">,</span> <span class="ss">total: </span><span class="n">pages</span><span class="p">.</span><span class="nf">size</span> <span class="c1"># report progress</span>
      <span class="n">page</span><span class="p">.</span><span class="nf">text</span>
    <span class="k">end</span><span class="p">.</span><span class="nf">join</span><span class="p">(</span><span class="s2">"</span><span class="se">\n</span><span class="s2">"</span><span class="p">)</span>
  <span class="k">end</span>
<span class="k">end</span>

<span class="n">chat</span><span class="p">.</span><span class="nf">with_tools</span><span class="p">(</span><span class="no">ReadReport</span><span class="p">).</span><span class="nf">after_tool_progress</span> <span class="k">do</span> <span class="o">|</span><span class="n">tool_call</span><span class="p">,</span> <span class="n">progress</span><span class="o">|</span> <span class="c1"># receives every update</span>
  <span class="nb">puts</span> <span class="s2">"</span><span class="si">#{</span><span class="n">tool_call</span><span class="p">.</span><span class="nf">name</span><span class="si">}</span><span class="s2">: </span><span class="si">#{</span><span class="n">progress</span><span class="p">.</span><span class="nf">message</span><span class="si">}</span><span class="s2">"</span>
<span class="k">end</span>
</code></pre></div></div>

<p>MCP tools report through the same callback. See <a href="https://rubyllm.com/tool-execution/#reporting-progress">Reporting Progress</a>.</p>

<h2 id="opentelemetry">OpenTelemetry Tracing</h2>

<p>One line sends every model call, tool run, and workflow as a span to the tracing backend you already use:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="no">RubyLLM</span><span class="o">::</span><span class="no">OpenTelemetry</span><span class="p">.</span><span class="nf">enable</span>
</code></pre></div></div>

<p>Spans join the current trace, so the HTTP call your tool makes nests under that tool. They carry metadata such as models, tokens, and tool names, and never prompts, responses, or tool arguments. The <a href="https://rubyllm.com/opentelemetry/">OpenTelemetry guide</a> has the full span reference.</p>

<h2 id="smaller-changes">Smaller Changes</h2>

<ul>
  <li><strong>Hetzner</strong> is provider number nineteen: <code class="language-plaintext highlighter-rouge">RubyLLM.chat(model: "Qwen3.8-27B", provider: :hetzner)</code>.</li>
  <li><strong>Switching providers mid-conversation</strong> works even in the middle of a tool round: each model receives only the content it can read.</li>
  <li><strong>Files a provider can’t read</strong>, such as Word documents, go through <code class="language-plaintext highlighter-rouge">convert_unsupported_attachments</code>, which sends your converted copy while the conversation keeps the original.</li>
  <li><strong>Cache lifetimes per boundary</strong>: <code class="language-plaintext highlighter-rouge">cache_until_here(ttl: "1h")</code> keeps a stable prefix cached longer than the rest of the chat.</li>
  <li><strong>Prompt partials</strong>: prompt templates <code class="language-plaintext highlighter-rouge">render</code> shared pieces the way Action View does.</li>
  <li><strong>Per-tenant agents</strong>: a <code class="language-plaintext highlighter-rouge">context</code> block can use the agent’s inputs, so each workspace can bring its own API key. Thanks to mikemikimike (#903).</li>
  <li><strong>A secondary database</strong> can hold RubyLLM’s supporting records next to your chats.</li>
  <li><strong>Usage beyond chats</strong>: in Rails, embeddings, transcriptions, and other one-shot calls go into the usage ledger too.</li>
  <li><strong><code class="language-plaintext highlighter-rouge">error.request_shape</code></strong> lists every turn’s parts and sizes when a provider rejects a request.</li>
  <li><strong>Provider uploads are reused</strong> across processes in Rails, so a large PDF isn’t uploaded again on every job.</li>
  <li><strong>Perplexity chat runs on the Agent API</strong>, since Sonar retires.</li>
  <li><strong>Ruby 3.2 or later</strong> is required, since 3.1 reached end of life.</li>
  <li><strong>JSON 3 is allowed</strong>, thanks to Filipe Kalicki (#968), who also made model lookups use an index (#981).</li>
</ul>

<h2 id="upgrading">Upgrading from 2.0</h2>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">gem</span> <span class="s2">"ruby_llm"</span><span class="p">,</span> <span class="s2">"~&gt; 2.1.0"</span>
</code></pre></div></div>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>bundle update ruby_llm
bin/rails generate ruby_llm:upgrade
bin/rails db:encryption:init   <span class="c"># only for MCP OAuth, if your app has no encryption keys yet</span>
bin/rails db:migrate
</code></pre></div></div>

<p>Most 2.0 apps need no code changes. The few that do are listed in the <a href="https://rubyllm.com/upgrading/">upgrade guide</a>, and everything new is in <a href="https://rubyllm.com/whats-new-in-2-1/">What’s New in 2.1</a>.</p>

<p>Thanks to everyone who sent code for this release: Andrii Furmanets, Andrey Samsonov, Andy Wang, Anton Kopylov, Filipe Kalicki, Guilherme Lages Santos, Islam Gagiev, Kieran Klaassen, Marc Köhlbrugge, mikemikimike, Mikhail Topolskiy, Muhammad Zain Ul Abidin, Paul Arterburn, and Viktor Schmidt.</p>]]></content><author><name>Carmine Paolino</name></author><category term="Ruby" /><category term="AI" /><category term="LLM" /><category term="Rails" /><category term="Open Source" /><category term="RubyLLM" /><category term="MCP" /><summary type="html"><![CDATA[RubyLLM 2.1 does what LangChain, LangGraph, and LangSmith do together: an MCP client with per-user OAuth, tool search, typed judgments, evaluations, and OpenTelemetry tracing, in one Ruby gem.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://paolino.me/images/rubyllm-2.1.png" /><media:content medium="image" url="https://paolino.me/images/rubyllm-2.1.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">RubyLLM 2.0: Tool Approval, Video, Speech, Citations, and Cost Tracking</title><link href="https://paolino.me/rubyllm-2-0/" rel="alternate" type="text/html" title="RubyLLM 2.0: Tool Approval, Video, Speech, Citations, and Cost Tracking" /><published>2026-10-05T00:00:00+00:00</published><updated>2026-10-14T14:33:02+00:00</updated><id>https://paolino.me/rubyllm-2-0</id><content type="html" xml:base="https://paolino.me/rubyllm-2-0/"><![CDATA[<p>RubyLLM 2.0 is the biggest release since 1.0. It starts with tool approval:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">class</span> <span class="nc">RefundOrder</span> <span class="o">&lt;</span> <span class="no">RubyLLM</span><span class="o">::</span><span class="no">Tool</span>
  <span class="n">description</span> <span class="s2">"Refunds an order"</span>
  <span class="n">parameter</span> <span class="ss">:order_id</span><span class="p">,</span> <span class="ss">description: </span><span class="s2">"ID of the order to refund"</span>
  <span class="n">requires_approval</span> <span class="c1"># that's all it takes</span>

  <span class="k">def</span> <span class="nf">execute</span><span class="p">(</span><span class="n">order_id</span><span class="p">:,</span> <span class="ss">tool_call: </span><span class="kp">nil</span><span class="p">)</span>
    <span class="no">Refunds</span><span class="p">.</span><span class="nf">issue</span><span class="p">(</span><span class="n">order_id</span><span class="p">:,</span> <span class="ss">idempotency_key: </span><span class="n">tool_call</span><span class="p">.</span><span class="nf">id</span><span class="p">)</span>
  <span class="k">end</span>
<span class="k">end</span>

<span class="k">class</span> <span class="nc">SupportAgent</span> <span class="o">&lt;</span> <span class="no">RubyLLM</span><span class="o">::</span><span class="no">Agent</span>
  <span class="n">chat_model</span> <span class="no">Chat</span>
  <span class="n">tools</span> <span class="no">RefundOrder</span>
<span class="k">end</span>

<span class="n">chat</span> <span class="o">=</span> <span class="no">SupportAgent</span><span class="p">.</span><span class="nf">create!</span>
<span class="n">chat</span><span class="p">.</span><span class="nf">ask</span> <span class="s2">"I was charged twice for order 42."</span> <span class="c1"># stops before refunding</span>

<span class="c1"># later, when the user approves</span>
<span class="n">chat</span> <span class="o">=</span> <span class="no">SupportAgent</span><span class="p">.</span><span class="nf">find</span><span class="p">(</span><span class="n">chat</span><span class="p">.</span><span class="nf">id</span><span class="p">)</span>
<span class="n">chat</span><span class="p">.</span><span class="nf">approve</span><span class="p">(</span><span class="n">chat</span><span class="p">.</span><span class="nf">pending_approvals</span><span class="p">.</span><span class="nf">first</span><span class="p">)</span>
<span class="n">chat</span><span class="p">.</span><span class="nf">complete</span> <span class="c1"># issues the refund and answers</span>
</code></pre></div></div>

<p>The pending call is saved in your database, so the approval can come tomorrow, from another process, after two deploys.</p>

<p>2.0 also generates video and speech, reads scanned documents, reranks search results, runs provider-hosted tools with typed citations, accounts for every provider attempt (including the ones that failed), and works across seventeen providers.</p>

<p>There’s also a <a href="https://github.com/crmne/ruby_llm/releases/download/v2.0.0/rubyllm-tour.mp4">two-minute tour of 2.0</a>.</p>

<p>Each section below shows one feature and links to its guide.</p>

<ul>
  <li><a href="#tool-approval-and-durable-agents">Tool approval and durable agents</a></li>
  <li><a href="#the-agentic-loop">The agentic loop</a></li>
  <li><a href="#new-operations">New operations: video, OCR, reranking, tokens</a></li>
  <li><a href="#speech-and-transcription">Speech and transcription</a></li>
  <li><a href="#provider-tools">Provider tools</a></li>
  <li><a href="#citations">Citations</a></li>
  <li><a href="#files-and-attachments">Files and attachments</a></li>
  <li><a href="#cost-and-usage">Cost and usage</a></li>
  <li><a href="#fallbacks-cancellation-and-errors">Fallbacks, cancellation, and errors</a></li>
  <li><a href="#prompt-caching">Prompt caching</a></li>
  <li><a href="#batches">Batches</a></li>
  <li><a href="#owning-the-transcript">Owning the transcript</a></li>
  <li><a href="#providers-and-protocols">Providers and protocols</a></li>
  <li><a href="#rails-table-ownership">Rails table ownership</a></li>
  <li><a href="#prompt-templates">Prompt templates</a></li>
  <li><a href="#workflows-and-instrumentation">Workflows and instrumentation</a></li>
  <li><a href="#coding-assistant-skill">Coding assistant skill</a></li>
  <li><a href="#upgrading">Upgrading from 1.16</a></li>
  <li><a href="#get-it">Get it</a></li>
</ul>

<h2 id="tool-approval-and-durable-agents">Tool Approval and Durable Agents</h2>

<p>Declare <code class="language-plaintext highlighter-rouge">requires_approval</code> on a tool and the loop stops before running it. <code class="language-plaintext highlighter-rouge">chat.pending_approvals</code> lists the waiting calls with their arguments, and <code class="language-plaintext highlighter-rouge">approve</code> or <code class="language-plaintext highlighter-rouge">deny</code> decides. With <code class="language-plaintext highlighter-rouge">acts_as_chat</code>, the call and its decision are database rows, so the approval can come from any process:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">class</span> <span class="nc">ApprovalsController</span> <span class="o">&lt;</span> <span class="no">ApplicationController</span>
  <span class="k">def</span> <span class="nf">create</span>
    <span class="n">chat</span> <span class="o">=</span> <span class="no">Chat</span><span class="p">.</span><span class="nf">find</span><span class="p">(</span><span class="n">params</span><span class="p">[</span><span class="ss">:chat_id</span><span class="p">])</span>
    <span class="n">chat</span><span class="p">.</span><span class="nf">approve</span><span class="p">(</span><span class="n">params</span><span class="p">[</span><span class="ss">:tool_call_id</span><span class="p">])</span> <span class="c1"># or chat.deny(...)</span>
    <span class="no">CompleteJob</span><span class="p">.</span><span class="nf">perform_later</span><span class="p">(</span><span class="n">chat</span><span class="p">.</span><span class="nf">id</span><span class="p">)</span>
  <span class="k">end</span>
<span class="k">end</span>

<span class="k">class</span> <span class="nc">CompleteJob</span> <span class="o">&lt;</span> <span class="no">ApplicationJob</span>
  <span class="k">def</span> <span class="nf">perform</span><span class="p">(</span><span class="n">chat_id</span><span class="p">)</span>
    <span class="no">SupportAgent</span><span class="p">.</span><span class="nf">find</span><span class="p">(</span><span class="n">chat_id</span><span class="p">).</span><span class="nf">complete</span> <span class="c1"># resumes where it stopped</span>
  <span class="k">end</span>
<span class="k">end</span>
</code></pre></div></div>

<p>There’s no workflow engine and no state machine to serialize: the transcript holds the state. The <a href="https://rubyllm.com/tool-execution/#requiring-approval">tool approval guide</a> and <a href="https://rubyllm.com/durable-agents/">durable agents guide</a> cover the full flow.</p>

<h2 id="the-agentic-loop">The Agentic Loop</h2>

<p><code class="language-plaintext highlighter-rouge">ask</code> still runs the whole agentic loop for you. When you want control, 2.0 breaks it into verbs (<code class="language-plaintext highlighter-rouge">ask_later</code>, <code class="language-plaintext highlighter-rouge">generate</code>, <code class="language-plaintext highlighter-rouge">run_tools</code>, <code class="language-plaintext highlighter-rouge">step</code>, <code class="language-plaintext highlighter-rouge">complete</code>, <code class="language-plaintext highlighter-rouge">cancel</code>), and each one reads the persisted messages to decide what to do next, so you can run one step per job:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">chat</span> <span class="o">=</span> <span class="no">RubyLLM</span><span class="p">.</span><span class="nf">chat</span><span class="p">.</span><span class="nf">with_tools</span><span class="p">(</span><span class="no">SearchDocs</span><span class="p">).</span><span class="nf">ask_later</span><span class="p">(</span><span class="s2">"How do I configure webhooks?"</span><span class="p">)</span>
<span class="n">chat</span><span class="p">.</span><span class="nf">step</span> <span class="k">until</span> <span class="n">chat</span><span class="p">.</span><span class="nf">complete?</span> <span class="o">||</span> <span class="n">chat</span><span class="p">.</span><span class="nf">awaiting_approval?</span>
</code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">halt</code> and <code class="language-plaintext highlighter-rouge">RubyLLM::Tool::Halt</code> are gone: your loop decides when to stop. I wrote about this in detail in <a href="/rubyllm-2-0-agentic-loop/">The Agentic Loop, Exposed</a>.</p>

<h2 id="new-operations">New Operations</h2>

<p>2.0 adds video, speech, OCR, reranking, multimodal embeddings, and tokenization. None of them needs a chat:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="no">RubyLLM</span><span class="p">.</span><span class="nf">animate</span><span class="p">(</span><span class="s2">"A red panda typing Ruby code"</span><span class="p">).</span><span class="nf">save</span><span class="p">(</span><span class="s2">"panda.mp4"</span><span class="p">)</span>
<span class="no">RubyLLM</span><span class="p">.</span><span class="nf">speak</span><span class="p">(</span><span class="s2">"Welcome to the Ruby study group."</span><span class="p">).</span><span class="nf">save</span><span class="p">(</span><span class="s2">"welcome.mp3"</span><span class="p">)</span>
<span class="no">RubyLLM</span><span class="p">.</span><span class="nf">ocr</span><span class="p">(</span><span class="s2">"scanned-contract.pdf"</span><span class="p">).</span><span class="nf">markdown</span>
<span class="no">RubyLLM</span><span class="p">.</span><span class="nf">rerank</span><span class="p">(</span><span class="s2">"How do I reset my password?"</span><span class="p">,</span> <span class="n">documents</span><span class="p">,</span> <span class="ss">model: </span><span class="s2">"rerank-v3.5"</span><span class="p">)</span>
<span class="no">RubyLLM</span><span class="p">.</span><span class="nf">embed</span><span class="p">(</span><span class="s2">"A red panda"</span><span class="p">,</span> <span class="ss">with: </span><span class="s2">"panda.jpg"</span><span class="p">,</span> <span class="ss">model: </span><span class="s2">"gemini-embedding-2"</span><span class="p">)</span>
<span class="no">RubyLLM</span><span class="p">.</span><span class="nf">tokenize</span><span class="p">(</span><span class="s2">"Hello, Ruby!"</span><span class="p">,</span> <span class="ss">model: </span><span class="s2">"grok-4.3"</span><span class="p">).</span><span class="nf">ids</span>
</code></pre></div></div>

<p>Each one has a guide: <a href="https://rubyllm.com/video-generation/">video</a>, <a href="https://rubyllm.com/ocr/">OCR</a>, <a href="https://rubyllm.com/rerank/">reranking</a>, <a href="https://rubyllm.com/embeddings/">embeddings</a>, and <a href="https://rubyllm.com/tokenization/">tokenization</a>.</p>

<h2 id="speech-and-transcription">Speech and Transcription</h2>

<p>2.0 adds text to speech with <code class="language-plaintext highlighter-rouge">RubyLLM.speak</code>, and transcription gains streaming, speaker labels, and word timestamps. Together they let a Rails action answer a voice message with audio:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">def</span> <span class="nf">create</span>
  <span class="n">audio</span> <span class="o">=</span> <span class="n">params</span><span class="p">[</span><span class="ss">:audio</span><span class="p">]</span>
  <span class="k">return</span> <span class="n">head</span> <span class="ss">:bad_request</span> <span class="k">unless</span> <span class="n">audio</span><span class="p">.</span><span class="nf">is_a?</span><span class="p">(</span><span class="no">ActionDispatch</span><span class="o">::</span><span class="no">Http</span><span class="o">::</span><span class="no">UploadedFile</span><span class="p">)</span>

  <span class="n">question</span> <span class="o">=</span> <span class="no">RubyLLM</span><span class="p">.</span><span class="nf">transcribe</span><span class="p">(</span><span class="n">audio</span><span class="p">).</span><span class="nf">text</span>
  <span class="n">answer</span> <span class="o">=</span> <span class="no">Current</span><span class="p">.</span><span class="nf">user</span><span class="p">.</span><span class="nf">support_chat</span><span class="p">.</span><span class="nf">ask</span><span class="p">(</span><span class="n">question</span><span class="p">).</span><span class="nf">content</span>

  <span class="n">speech</span> <span class="o">=</span> <span class="no">RubyLLM</span><span class="p">.</span><span class="nf">speak</span><span class="p">(</span><span class="n">answer</span><span class="p">)</span> <span class="c1"># text to speech</span>
  <span class="n">send_data</span> <span class="n">speech</span><span class="p">.</span><span class="nf">to_blob</span><span class="p">,</span> <span class="ss">type: </span><span class="n">speech</span><span class="p">.</span><span class="nf">mime_type</span><span class="p">,</span> <span class="ss">disposition: </span><span class="s2">"inline"</span>
<span class="k">end</span>
</code></pre></div></div>

<p>See the <a href="https://rubyllm.com/text-to-speech/">text to speech guide</a> and the <a href="https://rubyllm.com/audio-transcription/">transcription guide</a>.</p>

<h2 id="provider-tools">Provider Tools</h2>

<p><code class="language-plaintext highlighter-rouge">with_provider_tools</code> turns on tools the provider runs on its own infrastructure, like web search, code execution, file search, and remote MCP servers. The aliases are portable, so you can switch models without changing the code:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">chat</span> <span class="o">=</span> <span class="no">RubyLLM</span><span class="p">.</span><span class="nf">chat</span><span class="p">(</span><span class="ss">model: </span><span class="s2">"claude-sonnet-5"</span><span class="p">).</span><span class="nf">with_provider_tools</span><span class="p">(</span><span class="ss">:web_search</span><span class="p">)</span> <span class="c1"># runs on Anthropic's side</span>
<span class="n">response</span> <span class="o">=</span> <span class="n">chat</span><span class="p">.</span><span class="nf">ask</span> <span class="s2">"What changed in the latest Ruby release?"</span>

<span class="n">response</span><span class="p">.</span><span class="nf">citations</span><span class="p">.</span><span class="nf">each</span> <span class="p">{</span> <span class="o">|</span><span class="n">citation</span><span class="o">|</span> <span class="nb">puts</span> <span class="s2">"</span><span class="si">#{</span><span class="n">citation</span><span class="p">.</span><span class="nf">title</span><span class="si">}</span><span class="s2">: </span><span class="si">#{</span><span class="n">citation</span><span class="p">.</span><span class="nf">url</span><span class="si">}</span><span class="s2">"</span> <span class="p">}</span>
</code></pre></div></div>

<p>When OpenAI or Azure calls a tool on a remote MCP server, the call can wait in the same <code class="language-plaintext highlighter-rouge">pending_approvals</code> list as your Ruby tools. <code class="language-plaintext highlighter-rouge">RubyLLM.research_later</code> starts a hosted deep research agent and returns a job ID you can check from any process. The <a href="https://rubyllm.com/provider-tools/">provider tools guide</a> and the <a href="https://rubyllm.com/hosted-research/">hosted research guide</a> have the details.</p>

<h2 id="citations">Citations</h2>

<p>Every provider formats citations differently. RubyLLM turns them all into <code class="language-plaintext highlighter-rouge">RubyLLM::Citation</code>, from documents and from web search, and your own RAG tools can return <code class="language-plaintext highlighter-rouge">RubyLLM::SearchResults</code> to make their results citable:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">chat</span> <span class="o">=</span> <span class="no">RubyLLM</span><span class="p">.</span><span class="nf">chat</span><span class="p">(</span><span class="ss">model: </span><span class="s2">"claude-sonnet-5"</span><span class="p">).</span><span class="nf">with_citations</span> <span class="c1"># document citations</span>
<span class="n">response</span> <span class="o">=</span> <span class="n">chat</span><span class="p">.</span><span class="nf">ask</span> <span class="s2">"What are the termination conditions?"</span><span class="p">,</span> <span class="ss">with: </span><span class="s2">"contract.pdf"</span>

<span class="n">response</span><span class="p">.</span><span class="nf">citations</span><span class="p">.</span><span class="nf">each</span> <span class="k">do</span> <span class="o">|</span><span class="n">citation</span><span class="o">|</span>
  <span class="nb">puts</span> <span class="s2">"p. </span><span class="si">#{</span><span class="n">citation</span><span class="p">.</span><span class="nf">start_page</span><span class="si">}</span><span class="s2">: </span><span class="si">#{</span><span class="n">citation</span><span class="p">.</span><span class="nf">cited_text</span><span class="si">}</span><span class="s2">"</span>
<span class="k">end</span>
</code></pre></div></div>

<p>The <a href="https://rubyllm.com/citations/">citations guide</a> has a footnote renderer you can copy.</p>

<h2 id="files-and-attachments">Files and Attachments</h2>

<p><code class="language-plaintext highlighter-rouge">RubyLLM.upload</code> sends a file to the provider once, and <code class="language-plaintext highlighter-rouge">with:</code> takes the result like a path. Files too big to send inline are uploaded for you, and tools can now return files too:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">manual</span> <span class="o">=</span> <span class="no">RubyLLM</span><span class="p">.</span><span class="nf">upload</span><span class="p">(</span><span class="s2">"manual.pdf"</span><span class="p">,</span> <span class="ss">provider: :anthropic</span><span class="p">)</span> <span class="c1"># upload once</span>

<span class="n">chat</span> <span class="o">=</span> <span class="no">RubyLLM</span><span class="p">.</span><span class="nf">chat</span><span class="p">(</span><span class="ss">model: </span><span class="s2">"claude-sonnet-5"</span><span class="p">)</span>
<span class="n">chat</span><span class="p">.</span><span class="nf">ask</span> <span class="s2">"Summarize the manual."</span><span class="p">,</span> <span class="ss">with: </span><span class="n">manual</span>
<span class="n">chat</span><span class="p">.</span><span class="nf">ask</span> <span class="s2">"What does the warranty cover?"</span>
</code></pre></div></div>

<p>See the <a href="https://rubyllm.com/files/">files guide</a> and the <a href="https://rubyllm.com/attachments/">attachments guide</a>.</p>

<h2 id="cost-and-usage">Cost and Usage</h2>

<p>2.0 records tokens and cost per provider attempt, because providers bill attempts: retries, fallbacks, and cancelled streams all count. In Rails, each attempt is a row in <code class="language-plaintext highlighter-rouge">ruby_llm_usages</code>, and an unknown price is <code class="language-plaintext highlighter-rouge">nil</code>, not zero:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">chat</span> <span class="o">=</span> <span class="no">RubyLLM</span><span class="p">.</span><span class="nf">chat</span><span class="p">.</span><span class="nf">with_fallbacks</span><span class="p">(</span><span class="s2">"claude-sonnet-5"</span><span class="p">)</span>
<span class="n">response</span> <span class="o">=</span> <span class="n">chat</span><span class="p">.</span><span class="nf">ask</span> <span class="s2">"Explain Ruby fibers in one paragraph."</span>

<span class="n">response</span><span class="p">.</span><span class="nf">tokens</span><span class="p">.</span><span class="nf">input</span>
<span class="n">response</span><span class="p">.</span><span class="nf">cost</span><span class="p">.</span><span class="nf">total</span>
<span class="n">chat</span><span class="p">.</span><span class="nf">cost</span><span class="p">.</span><span class="nf">total</span> <span class="c1"># every attempt, including the ones that failed</span>
</code></pre></div></div>

<p>The <a href="https://rubyllm.com/cost-and-usage-tracking/">Tokens and Costs guide</a> explains what each total includes.</p>

<h2 id="fallbacks-cancellation-and-errors">Fallbacks, Cancellation, and Errors</h2>

<p><code class="language-plaintext highlighter-rouge">with_fallbacks</code> retries a failed request on backup models, in order, with the same conversation, tools, and settings. <code class="language-plaintext highlighter-rouge">chat.cancel</code> stops a run, and in Rails it works from another process through the database, so a stop button can end a streaming job. Agents declare error handlers once with <code class="language-plaintext highlighter-rouge">rescue_from</code>.</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">chat</span> <span class="o">=</span> <span class="no">RubyLLM</span><span class="p">.</span><span class="nf">chat</span><span class="p">(</span><span class="ss">model: </span><span class="s2">"claude-sonnet-5"</span><span class="p">)</span>
  <span class="p">.</span><span class="nf">with_fallbacks</span><span class="p">(</span><span class="s2">"gpt-5.6"</span><span class="p">,</span> <span class="s2">"gemini-3.7-flash"</span><span class="p">)</span> <span class="c1"># tried in order if Claude fails</span>

<span class="n">response</span> <span class="o">=</span> <span class="n">chat</span><span class="p">.</span><span class="nf">ask</span> <span class="s2">"Summarize this incident report."</span>
</code></pre></div></div>

<p>The <a href="https://rubyllm.com/error-handling/">error handling guide</a> covers fallbacks and errors, and <a href="https://rubyllm.com/rails-streaming/#cancelling-a-background-stream">Rails streaming</a> covers the stop button.</p>

<h2 id="prompt-caching">Prompt Caching</h2>

<p><code class="language-plaintext highlighter-rouge">with_caching</code> gives prompt caching one API across providers, and <code class="language-plaintext highlighter-rouge">cache_until_here</code> marks an explicit cache boundary when you know where your reusable prefix ends:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">chat</span> <span class="o">=</span> <span class="no">RubyLLM</span><span class="p">.</span><span class="nf">chat</span><span class="p">(</span><span class="ss">model: </span><span class="s2">"claude-sonnet-5"</span><span class="p">).</span><span class="nf">with_caching</span><span class="p">(</span><span class="ss">ttl: </span><span class="s2">"1h"</span><span class="p">)</span>

<span class="n">chat</span><span class="p">.</span><span class="nf">with_instructions</span><span class="p">(</span><span class="n">analysis_prompt</span><span class="p">).</span><span class="nf">cache_until_here</span> <span class="c1"># cache boundary</span>
<span class="n">chat</span><span class="p">.</span><span class="nf">add_message</span><span class="p">(</span><span class="ss">role: :user</span><span class="p">,</span> <span class="ss">content: </span><span class="n">contract_text</span><span class="p">).</span><span class="nf">cache_until_here</span>

<span class="n">chat</span><span class="p">.</span><span class="nf">ask</span> <span class="s2">"Does clause 14 conflict with the termination terms in clause 3?"</span>
<span class="n">chat</span><span class="p">.</span><span class="nf">ask</span> <span class="s2">"Which clauses mention liability caps?"</span>
</code></pre></div></div>

<p>The <a href="https://rubyllm.com/prompt-caching/">prompt caching guide</a> has the details.</p>

<h2 id="batches">Batches</h2>

<p>Batch APIs cost less than interactive requests. <code class="language-plaintext highlighter-rouge">RubyLLM.batch</code> submits ordinary chats to them, and in Rails the answers are saved through the same callbacks as a normal <code class="language-plaintext highlighter-rouge">ask</code>:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">chats</span> <span class="o">=</span> <span class="n">tickets</span><span class="p">.</span><span class="nf">map</span> <span class="k">do</span> <span class="o">|</span><span class="n">ticket</span><span class="o">|</span>
  <span class="no">RubyLLM</span><span class="p">.</span><span class="nf">chat</span><span class="p">(</span><span class="ss">model: </span><span class="s2">"claude-haiku-4-5"</span><span class="p">)</span>
    <span class="p">.</span><span class="nf">with_instructions</span><span class="p">(</span><span class="s2">"Classify this ticket as billing, bug, or feature request."</span><span class="p">)</span>
    <span class="p">.</span><span class="nf">ask_later</span><span class="p">(</span><span class="n">ticket</span><span class="p">.</span><span class="nf">body</span><span class="p">)</span>
<span class="k">end</span>

<span class="n">batch</span> <span class="o">=</span> <span class="no">RubyLLM</span><span class="p">.</span><span class="nf">batch</span><span class="p">(</span><span class="n">chats</span><span class="p">)</span> <span class="c1"># submits them all at once</span>
<span class="n">batch</span><span class="p">.</span><span class="nf">id</span> <span class="c1"># save this</span>
</code></pre></div></div>

<p>Later, <code class="language-plaintext highlighter-rouge">RubyLLM::Batch.find</code> picks the batch up from any process. The <a href="https://rubyllm.com/batches/">batch guide</a> covers polling, results, and setup.</p>

<h2 id="owning-the-transcript">Owning the Transcript</h2>

<p><code class="language-plaintext highlighter-rouge">chat.messages = messages_for_model</code> replaces the history you send, so you can summarize old turns or redact values, and <code class="language-plaintext highlighter-rouge">with_compaction</code> lets providers that support it compact long conversations themselves. <code class="language-plaintext highlighter-rouge">before_request</code> edits the final payload, and <code class="language-plaintext highlighter-rouge">render</code> shows it without calling the model:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">chat</span> <span class="o">=</span> <span class="no">RubyLLM</span><span class="p">.</span><span class="nf">chat</span><span class="p">(</span><span class="ss">model: </span><span class="s2">"gpt-5.6"</span><span class="p">)</span>
  <span class="p">.</span><span class="nf">ask_later</span><span class="p">(</span><span class="s2">"Summarize the changes."</span><span class="p">)</span>

<span class="n">chat</span><span class="p">.</span><span class="nf">before_request</span> <span class="k">do</span> <span class="o">|</span><span class="n">payload</span><span class="o">|</span>
  <span class="n">payload</span><span class="p">[</span><span class="ss">:metadata</span><span class="p">]</span> <span class="o">=</span> <span class="p">{</span> <span class="ss">review_id: </span><span class="s2">"review-42"</span> <span class="p">}</span>
<span class="k">end</span>

<span class="n">chat</span><span class="p">.</span><span class="nf">render</span><span class="p">[</span><span class="ss">:metadata</span><span class="p">]</span> <span class="c1"># =&gt; { review_id: "review-42" }</span>
<span class="n">chat</span><span class="p">.</span><span class="nf">complete</span>
</code></pre></div></div>

<p>Details are in the <a href="https://rubyllm.com/chat-request-control/">request control guide</a> and the <a href="https://rubyllm.com/rails-persistence/#separate-user-and-llm-transcripts">persistence guide</a>.</p>

<h2 id="providers-and-protocols">Providers and Protocols</h2>

<p>Cohere, Ollama Cloud, ElevenLabs, and Deepgram join, bringing the total to seventeen, and built-in support went from 170 provider-feature pairs to 395 (<a href="https://rubyllm.com/provider-coverage/">coverage matrix</a>). Providers and protocols are now separate: a provider is the service you connect to, a protocol is the API it speaks.</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="no">RubyLLM</span><span class="p">.</span><span class="nf">chat</span><span class="p">(</span><span class="ss">model: </span><span class="s1">'gpt-5.4'</span><span class="p">)</span>                              <span class="c1"># OpenAI Responses API</span>
<span class="no">RubyLLM</span><span class="p">.</span><span class="nf">chat</span><span class="p">(</span><span class="ss">model: </span><span class="s1">'gpt-5.4'</span><span class="p">,</span> <span class="ss">protocol: :chat_completions</span><span class="p">)</span> <span class="c1"># same model, old API</span>
<span class="no">RubyLLM</span><span class="p">.</span><span class="nf">chat</span><span class="p">(</span><span class="ss">model: </span><span class="s1">'claude-opus-4-6'</span><span class="p">,</span> <span class="ss">provider: :vertexai</span><span class="p">)</span> <span class="c1"># Vertex AI, Anthropic protocol</span>
</code></pre></div></div>

<p>If the provider you need isn’t built in, <code class="language-plaintext highlighter-rouge">ruby_llm provider-gem Acme</code> generates a gem for it, with tests, CI, and a model catalog. I covered the design in <a href="/rubyllm-2-0-providers-and-protocols/">Providers, Protocols, and Provider Gems</a>.</p>

<h2 id="rails-table-ownership">Rails Table Ownership</h2>

<p>A fresh install now gives you two models instead of four. Chats and messages stay yours, and RubyLLM keeps models, tool calls, usage, and batches in its own <code class="language-plaintext highlighter-rouge">ruby_llm_</code> tables, the way Active Storage owns its records. The record classes are internal and the readers are public, so RubyLLM can change its storage without your app noticing:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># app/models/chat.rb</span>
<span class="k">class</span> <span class="nc">Chat</span> <span class="o">&lt;</span> <span class="no">ApplicationRecord</span>
  <span class="n">acts_as_chat</span>
  <span class="n">belongs_to</span> <span class="ss">:user</span>
<span class="k">end</span>

<span class="c1"># app/models/message.rb</span>
<span class="k">class</span> <span class="nc">Message</span> <span class="o">&lt;</span> <span class="no">ApplicationRecord</span>
  <span class="n">acts_as_message</span>
  <span class="n">has_many_attached</span> <span class="ss">:attachments</span>
<span class="k">end</span>
</code></pre></div></div>

<p>The <a href="https://rubyllm.com/rails-persistence/">Rails persistence guide</a> shows every association and reader.</p>

<h2 id="prompt-templates">Prompt Templates</h2>

<p>Prompts get a directory the way views do, <code class="language-plaintext highlighter-rouge">app/prompts</code>, and <code class="language-plaintext highlighter-rouge">RubyLLM.render_prompt</code> renders them. Agents pick up their instructions from it by convention, and Rails engines can ship their own prompts. Thanks to <a href="https://github.com/kryzhovnik">@kryzhovnik</a>, who extracted the renderer out of Agent’s private methods, which made this possible.</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">instructions</span> <span class="o">=</span> <span class="no">RubyLLM</span><span class="p">.</span><span class="nf">render_prompt</span><span class="p">(</span> <span class="c1"># renders app/prompts/support/instructions.txt.erb</span>
  <span class="s2">"support/instructions"</span><span class="p">,</span>
  <span class="ss">product_name: </span><span class="s2">"BillingHub"</span><span class="p">,</span>
  <span class="ss">customer_name: </span><span class="n">current_user</span><span class="p">.</span><span class="nf">name</span>
<span class="p">)</span>
</code></pre></div></div>

<p>The <a href="https://rubyllm.com/prompt-rendering/">prompt rendering guide</a> has the details.</p>

<h2 id="workflows-and-instrumentation">Workflows and Instrumentation</h2>

<p><code class="language-plaintext highlighter-rouge">RubyLLM.workflow</code> names a piece of work and tags every event inside it, so model calls, tool calls, and costs trace back to the run that caused them. Control flow stays plain Ruby, with no graph DSL. Instrumentation grew from five events to twenty.</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="no">RubyLLM</span><span class="p">.</span><span class="nf">workflow</span><span class="p">(</span><span class="s2">"Write article"</span><span class="p">,</span> <span class="ss">id: </span><span class="s2">"article-42"</span><span class="p">)</span> <span class="k">do</span> <span class="o">|</span><span class="n">workflow</span><span class="o">|</span> <span class="c1"># tags every event inside</span>
  <span class="n">notes</span> <span class="o">=</span> <span class="n">workflow</span><span class="p">.</span><span class="nf">step</span><span class="p">(</span><span class="s2">"Research"</span><span class="p">)</span> <span class="k">do</span>
    <span class="no">ResearchAgent</span><span class="p">.</span><span class="nf">new</span><span class="p">.</span><span class="nf">ask</span><span class="p">(</span><span class="n">topic</span><span class="p">).</span><span class="nf">content</span>
  <span class="k">end</span>

  <span class="n">workflow</span><span class="p">.</span><span class="nf">step</span><span class="p">(</span><span class="s2">"Draft"</span><span class="p">)</span> <span class="k">do</span>
    <span class="no">WriterAgent</span><span class="p">.</span><span class="nf">new</span><span class="p">.</span><span class="nf">ask</span><span class="p">(</span><span class="n">notes</span><span class="p">).</span><span class="nf">content</span>
  <span class="k">end</span>
<span class="k">end</span>
</code></pre></div></div>

<p>The <a href="https://rubyllm.com/instrumentation/">instrumentation guide</a> lists every event and payload field.</p>

<h2 id="coding-assistant-skill">Coding Assistant Skill</h2>

<p>The gem ships a RubyLLM skill for coding assistants, maintained alongside the code and guides. Install the copy that matches your bundle:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>npx skills add <span class="s2">"</span><span class="si">$(</span>bundle show ruby_llm<span class="si">)</span><span class="s2">"</span> <span class="nt">--skill</span> rubyllm
</code></pre></div></div>

<p>Your assistant stops writing 1.x method names from its training data and stops rebuilding things RubyLLM already does. <a href="https://rubyllm.com/ai-coding-assistants/">Setup details</a>.</p>

<h2 id="upgrading">Upgrading</h2>

<p>Upgrade from 1.16; if you’re on something older, step through the minor releases first. Pin the 2.0 series, because the 1.16 upgrade generator ships with 2.0 only, and finish this upgrade, cleanup included, before you move to 2.1:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">gem</span> <span class="s2">"ruby_llm"</span><span class="p">,</span> <span class="s2">"~&gt; 2.0.0"</span>
</code></pre></div></div>

<p>Most code changes are renames to fully spelled-out names, such as <code class="language-plaintext highlighter-rouge">desc</code> to <code class="language-plaintext highlighter-rouge">description</code>, <code class="language-plaintext highlighter-rouge">param</code> to <code class="language-plaintext highlighter-rouge">parameter</code>, and <code class="language-plaintext highlighter-rouge">with_params</code> to <code class="language-plaintext highlighter-rouge">with_provider_options</code>. For Rails persistence, <code class="language-plaintext highlighter-rouge">bin/rails generate ruby_llm:upgrade</code> writes the migrations. Rename mode, the default, moves your existing tables into RubyLLM’s ownership while AI activity is paused. Copy mode (<code class="language-plaintext highlighter-rouge">--mode copy</code>) builds the 2.0 tables next to the old ones while 1.16 keeps serving traffic, and keeps a way back to 1.16.</p>

<p>The <a href="https://github.com/crmne/ruby_llm/blob/v2.0.0/docs/_reference/upgrading.md">complete 2.0 upgrade guide</a> has every rename and the full procedure.</p>

<h2 id="get-it">Get It</h2>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>bundle add ruby_llm
</code></pre></div></div>

<p><a href="https://rubyllm.com/whats-new-in-2-0/">What’s New in 2.0</a> has working examples of everything above, the <a href="https://github.com/crmne/ruby_llm/blob/v2.0.0/docs/_reference/upgrading.md">upgrade guide</a> walks a Rails app from 1.16, and the <a href="https://rubyllm.com">documentation</a> covers the rest.</p>

<p>Thanks to everyone who tested the release candidates, filed issues, and sent code, including 22 people who made their first contribution during this cycle.</p>

<p><a href="/rubyllm-2-1/">RubyLLM 2.1</a> followed on October 8, at Deccan Queen on Rails in Pune.</p>]]></content><author><name>Carmine Paolino</name></author><category term="Ruby" /><category term="AI" /><category term="LLM" /><category term="Rails" /><category term="Open Source" /><category term="RubyLLM" /><summary type="html"><![CDATA[What's new in RubyLLM 2.0: tool approval and durable agents, video, speech, OCR, reranking, provider tools, citations, cost tracking, batches, caching, and the upgrade path from 1.16.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://paolino.me/images/rubyllm-2.0.png" /><media:content medium="image" url="https://paolino.me/images/rubyllm-2.0.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Berlin.rb: A New Monthly Ruby Meetup in Berlin</title><link href="https://paolino.me/berlin-rb/" rel="alternate" type="text/html" title="Berlin.rb: A New Monthly Ruby Meetup in Berlin" /><published>2026-09-02T00:00:00+00:00</published><updated>2026-09-02T16:41:46+00:00</updated><id>https://paolino.me/berlin-rb</id><content type="html" xml:base="https://paolino.me/berlin-rb/"><![CDATA[<p><a href="https://berlinrb.org">Berlin.rb</a> is a new monthly meetup for people who write Ruby, or are curious about it. A few of us from Berlin’s Ruby community are organizing talks, project show-and-tells, and time to meet other people who work in the same language. It’s free and open to anyone, whether you’ve been writing Ruby for fifteen years or installed it last week.</p>

<p><strong>The first one is Tuesday, September 8, 18:45, at Potsdamer Straße 121. Use the Grover entrance next to Rossmann and head to the third floor.</strong> The evening is hosted and sponsored by <a href="https://ablefy.io">ablefy</a>, with drinks and snacks provided. After that, the second Tuesday of every month.</p>

<p><a href="https://luma.com/lnmj7085">Register here.</a> If you can’t make it to Berlin, there’s a <a href="https://luma.com/psvh08jx">livestream</a> and it’ll be on <a href="https://www.youtube.com/@berlinrb_org">YouTube</a> afterwards.</p>

<h2 id="the-first-meetup">The first meetup</h2>

<p>I’m giving the first talk anywhere on <a href="https://rubyllm.com">RubyLLM</a> 2.0: <strong>RubyLLM 2.0: Beyond Agents</strong>.</p>

<p><strong>Paweł Strzałkowski</strong>, CTO at Visuality, is giving the second: <strong>HiFuMi: The Story of Building an Online Rails Apps Generator</strong>.</p>

<h2 id="why-another-one">Why another one</h2>

<p>Berlin already has <a href="https://www.rug-b.de">RUG::B</a>, a long-running Ruby user group. Berlin is big enough for both, and more Ruby events are a good thing.</p>

<p>Berlin.rb adds a predictable rhythm: second Tuesday, every month. Put it in your calendar once and stop checking.</p>

<h2 id="bigger-than-berlin">Bigger than Berlin</h2>

<p>We don’t want this to be just a room in Berlin.</p>

<ol>
  <li>
    <p>We’re livestreaming the meetup and publishing the talks on <a href="https://www.youtube.com/@berlinrb_org">YouTube</a> afterwards, so joining Berlin.rb doesn’t require being in Berlin.</p>
  </li>
  <li>
    <p>Berlin.rb is part of <a href="https://rubyeurope.com">Ruby Europe</a>, the umbrella bringing together Ruby communities across the continent and moving speakers between cities.</p>
  </li>
</ol>

<h2 id="come-talk">Come talk</h2>

<p>We want speakers! A deep technical talk, a lightning talk about something you built last weekend, a story about something that went badly in production. If you’ve never given a talk before, this is a good place for the first one.</p>

<p>Send a sentence or two to <a href="mailto:hello@berlinrb.org">hello@berlinrb.org</a> and we’ll take it from there.</p>

<h2 id="host-or-sponsor-us">Host or sponsor us</h2>

<p>We want to move around the city. Different neighbourhoods, different offices, so it’s easy to reach wherever you happen to live, and so you get to see where other Berlin Ruby teams actually work.</p>

<p>If your company has a space free on a weekday evening, or wants to cover food and drinks, we’d love to hear from you. Sponsorship is what keeps this free and open to everyone, and hosting is the easiest way to put your team in front of Berlin’s Ruby community.</p>

<p><a href="mailto:hello@berlinrb.org">hello@berlinrb.org</a></p>

<h2 id="the-people">The people</h2>

<p>Berlin.rb is put together by a group of us from around Berlin’s Ruby community. The current organizers are listed on <a href="https://berlinrb.org/#faq">berlinrb.org</a>.</p>

<p><a href="https://berlinrb.org">berlinrb.org</a> · <a href="https://luma.com/berlinrb">Luma</a> · <a href="https://www.youtube.com/@berlinrb_org">YouTube</a> · <a href="https://x.com/berlinrb_org">X</a> · <a href="https://bsky.app/profile/berlinrb.bsky.social">Bluesky</a> · <a href="https://www.linkedin.com/company/berlinrb">LinkedIn</a></p>

<p>See you on the 8th.</p>]]></content><author><name>Carmine Paolino</name></author><category term="Ruby" /><category term="Berlin" /><category term="Community" /><category term="Meetup" /><category term="Berlin.rb" /><summary type="html"><![CDATA[Berlin.rb is a new monthly meetup for Berlin's Ruby community. Free, second Tuesday of every month. The first one is September 8, with talks by Paweł Strzałkowski and I.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://paolino.me/images/berlinrb.png" /><media:content medium="image" url="https://paolino.me/images/berlinrb.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">RubyLLM 2.0: The Agentic Loop, Exposed</title><link href="https://paolino.me/rubyllm-2-0-agentic-loop/" rel="alternate" type="text/html" title="RubyLLM 2.0: The Agentic Loop, Exposed" /><published>2026-08-28T00:00:00+00:00</published><updated>2026-10-04T17:42:40+00:00</updated><id>https://paolino.me/rubyllm-2-0-agentic-loop</id><content type="html" xml:base="https://paolino.me/rubyllm-2-0-agentic-loop/"><![CDATA[<p>Strip any agent framework down and you find the same loop: call the model, run the tools it asked for, call the model again, stop when it answers without wanting a tool. RubyLLM has run that loop inside <code class="language-plaintext highlighter-rouge">ask</code> since 1.0. In 2.0, you can also control each step.</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># Run the agentic loop automatically</span>
<span class="n">response</span> <span class="o">=</span> <span class="no">RubyLLM</span><span class="p">.</span><span class="nf">chat</span><span class="p">(</span><span class="ss">model: </span><span class="s2">"claude-sonnet-4-6"</span><span class="p">)</span>
  <span class="p">.</span><span class="nf">with_tools</span><span class="p">(</span><span class="no">Weather</span><span class="p">)</span>
  <span class="p">.</span><span class="nf">ask</span><span class="p">(</span><span class="s2">"What's the weather in Paris?"</span><span class="p">)</span>
<span class="c1"># =&gt; #&lt;RubyLLM::Message role: :assistant, content: "Here's the current...</span>
</code></pre></div></div>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># Run the agentic loop manually</span>
<span class="n">chat</span> <span class="o">=</span> <span class="no">RubyLLM</span><span class="p">.</span><span class="nf">chat</span><span class="p">(</span><span class="ss">model: </span><span class="s2">"claude-sonnet-4-6"</span><span class="p">)</span>
  <span class="p">.</span><span class="nf">with_tools</span><span class="p">(</span><span class="no">Weather</span><span class="p">)</span>
  <span class="p">.</span><span class="nf">ask_later</span><span class="p">(</span><span class="s2">"What's the weather in Paris?"</span><span class="p">)</span>

<span class="n">chat</span><span class="p">.</span><span class="nf">step</span> <span class="k">until</span> <span class="n">chat</span><span class="p">.</span><span class="nf">complete?</span> <span class="o">||</span> <span class="n">chat</span><span class="p">.</span><span class="nf">awaiting_approval?</span>  <span class="c1"># generate, run_tools, generate</span>
<span class="n">chat</span><span class="p">.</span><span class="nf">messages</span><span class="p">.</span><span class="nf">last</span><span class="p">.</span><span class="nf">content</span>
<span class="c1"># =&gt; "Here's the current weather in **Paris, France**:\n\n- 🌡️ **Tempera...</span>
</code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">ask</code> still runs the loop for you, stopping when the answer is ready or a tool needs human approval. You can also call each part yourself:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">ask_later</code> stages your message without sending anything.</li>
  <li><code class="language-plaintext highlighter-rouge">generate</code> makes one model call and appends the response.</li>
  <li><code class="language-plaintext highlighter-rouge">run_tools</code> executes pending tool calls and appends their results without calling the model.</li>
  <li><code class="language-plaintext highlighter-rouge">step</code> runs pending tools if any are unanswered, otherwise it calls the model.</li>
  <li><code class="language-plaintext highlighter-rouge">complete?</code> tells you when the conversation is settled: the model answered without calling a tool.</li>
  <li><code class="language-plaintext highlighter-rouge">complete</code> steps until done or awaiting approval. <code class="language-plaintext highlighter-rouge">ask</code> is <code class="language-plaintext highlighter-rouge">ask_later</code> followed by <code class="language-plaintext highlighter-rouge">complete</code>.</li>
</ul>

<p>This lets you set an iteration budget, batch the next generation, wait for approval, or save progress and continue in another job. Your code can check what happened between calls.</p>

<h2 id="one-step-per-job">One Step Per Job</h2>

<p>Each verb decides what to do next by reading the persisted messages. That means the loop doesn’t need to live in one process, or one machine, or one deploy:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">class</span> <span class="nc">AgentTurnJob</span> <span class="o">&lt;</span> <span class="no">ApplicationJob</span>
  <span class="k">def</span> <span class="nf">perform</span><span class="p">(</span><span class="n">chat_id</span><span class="p">)</span>
    <span class="n">chat</span> <span class="o">=</span> <span class="no">Chat</span><span class="p">.</span><span class="nf">find</span><span class="p">(</span><span class="n">chat_id</span><span class="p">).</span><span class="nf">with_tools</span><span class="p">(</span><span class="no">Weather</span><span class="p">)</span>
    <span class="n">chat</span><span class="p">.</span><span class="nf">step</span>
    <span class="no">AgentTurnJob</span><span class="p">.</span><span class="nf">perform_later</span><span class="p">(</span><span class="n">chat_id</span><span class="p">)</span> <span class="k">unless</span> <span class="n">chat</span><span class="p">.</span><span class="nf">complete?</span> <span class="o">||</span> <span class="n">chat</span><span class="p">.</span><span class="nf">awaiting_approval?</span>
  <span class="k">end</span>
<span class="k">end</span>
</code></pre></div></div>

<p>Each step gets its own job and retry boundary. A long sequence can release the worker between steps; an individual provider request or tool still takes as long as it takes.</p>

<p>The loop is resumable mid-tool-round too. <code class="language-plaintext highlighter-rouge">run_tools</code> skips calls whose results have been saved. If a process dies after saving one result out of three, reloading the chat and calling <code class="language-plaintext highlighter-rouge">step</code> executes only the remaining two. If it dies after an external action succeeds but before saving its result, the tool can run again. Use <code class="language-plaintext highlighter-rouge">tool_call.id</code> as an idempotency key for writes. On Rails 8.1 and later, you can use ActiveJob Continuations to build on this: checkpoint after each move and an agent run survives a redeploy, resuming from the persisted messages with no cursor to manage.</p>

<p>Batches are the same idea at scale: a batch is <code class="language-plaintext highlighter-rouge">generate</code> deferred for many chats at once, with <code class="language-plaintext highlighter-rouge">run_tools</code> run locally between rounds.</p>

<h2 id="cancelable-generation">Cancelable generation</h2>

<p><code class="language-plaintext highlighter-rouge">chat.cancel</code> cancels a run from another thread. At the next checkpoint, before a model call, before a tool executes, or between streamed chunks, the run raises <code class="language-plaintext highlighter-rouge">RubyLLM::CancelledError</code> and clears the flag so the chat can be reused.</p>

<p>In Rails, <code class="language-plaintext highlighter-rouge">acts_as_chat</code> stores the cancellation request on the chat record, so the signal travels through the database. A stop button in your web process halts a background job mid-stream:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">class</span> <span class="nc">ChatsController</span> <span class="o">&lt;</span> <span class="no">ApplicationController</span>
  <span class="k">def</span> <span class="nf">cancel</span>
    <span class="n">current_user</span><span class="p">.</span><span class="nf">chats</span><span class="p">.</span><span class="nf">find</span><span class="p">(</span><span class="n">params</span><span class="p">[</span><span class="ss">:id</span><span class="p">]).</span><span class="nf">cancel</span>
    <span class="n">head</span> <span class="ss">:no_content</span>
  <span class="k">end</span>
<span class="k">end</span>
</code></pre></div></div>

<p>The job checks the chat record at cancellation checkpoints. It cannot interrupt arbitrary Ruby code inside a running tool; the next checkpoint observes the request.</p>

<h2 id="halt-is-gone">Halt Is Gone</h2>

<p>RubyLLM 1.x let a tool terminate the loop from the inside: return <code class="language-plaintext highlighter-rouge">halt("done")</code> and the conversation ended. That put control flow inside a return value, and it’s gone in 2.0, along with <code class="language-plaintext highlighter-rouge">RubyLLM::Tool::Halt</code>. Tools return results. Stopping belongs to the caller:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">until</span> <span class="n">chat</span><span class="p">.</span><span class="nf">complete?</span> <span class="o">||</span> <span class="n">chat</span><span class="p">.</span><span class="nf">awaiting_approval?</span>
  <span class="n">chat</span><span class="p">.</span><span class="nf">step</span>
  <span class="k">break</span> <span class="k">if</span> <span class="n">handed_off?</span> <span class="c1"># application-specific stopping condition</span>
<span class="k">end</span>
</code></pre></div></div>

<p>If what you want is one tool call per model response rather than a condition, <code class="language-plaintext highlighter-rouge">chat.with_tool_options(calls: :one)</code> does that. For a total round budget, count <code class="language-plaintext highlighter-rouge">step</code> or <code class="language-plaintext highlighter-rouge">generate</code> calls in the loop you control.</p>

<p>The full guide, including the workflow patterns built on these verbs, is at https://rubyllm.com/agentic-workflows/.</p>]]></content><author><name>Carmine Paolino</name></author><category term="Ruby" /><category term="AI" /><category term="LLM" /><category term="Rails" /><category term="Open Source" /><category term="RubyLLM" /><summary type="html"><![CDATA[RubyLLM 2.0 breaks ask into verbs you can drive yourself: stage a message, call the model once, run tools, step, resume mid-round, and cancel from anywhere.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://paolino.me/images/rubyllm-2.0-agentic-loop.png" /><media:content medium="image" url="https://paolino.me/images/rubyllm-2.0-agentic-loop.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">kamal-backup 1.0: A Backup Is Only Real After You Restore It</title><link href="https://paolino.me/kamal-backup-1-0/" rel="alternate" type="text/html" title="kamal-backup 1.0: A Backup Is Only Real After You Restore It" /><published>2026-08-27T00:00:00+00:00</published><updated>2026-08-27T16:05:07+00:00</updated><id>https://paolino.me/kamal-backup-1-0</id><content type="html" xml:base="https://paolino.me/kamal-backup-1-0/"><![CDATA[<p>I released <a href="https://kamal-backup.dev">kamal-backup</a> 1.0 today.</p>

<p>Not because the backup command works. That part worked months ago.</p>

<p>I called it 1.0 because I used it to move <a href="https://chatwithwork.com">Chat with Work</a>, the application that pays my bills, to a new Hetzner instance. The old host took the backup. The new host restored it under a temporary hostname. I opened the real application, checked the real data and files, and only then moved DNS.</p>

<p>A backup is only real after you restore it.</p>

<h2 id="the-migration-that-made-10">The migration that made 1.0</h2>

<p>The move found two bugs that a green backup log never could.</p>

<p>First, a fresh backup accessory on the new host could start its schedule before the restore and write a perfectly valid, completely empty snapshot into the same repository. Ask for <code class="language-plaintext highlighter-rouge">latest</code> during the migration and you could restore that one.</p>

<p>Second, Kamal had already run Rails’ <code class="language-plaintext highlighter-rouge">db:prepare</code> on the new host. PostgreSQL’s normal <code class="language-plaintext highlighter-rouge">pg_restore --clean</code> path could not reliably replace that prepared schema when target-only foreign keys got in the way. Drops failed, creates failed because objects still existed, data never loaded, and <code class="language-plaintext highlighter-rouge">pg_restore</code> could still look more successful than the database it left behind.</p>

<p>Those problems became the restore model in 1.0. A replacement host can boot its accessory with scheduled backups disabled. PostgreSQL restores remove the target’s user schemas first, recreate <code class="language-plaintext highlighter-rouge">public</code>, restore with a client matching the server, and fail if <code class="language-plaintext highlighter-rouge">pg_restore</code> reports ignored errors.</p>

<p>The workflow is now written down in the <a href="https://kamal-backup.dev/migrating-hosts/">host migration guide</a>: restore under a temporary hostname, verify the application, stop writes to the old host, take and restore a final backup if necessary, then move traffic.</p>

<h2 id="exact-means-exact">Exact means exact</h2>

<p>A restore should leave the target looking like the snapshot, not like the snapshot layered over whatever happened to be there already.</p>

<p>That promise now applies to every supported database:</p>

<ul>
  <li>PostgreSQL removes every non-system schema before restoring the custom-format dump.</li>
  <li>MySQL and MariaDB remove existing views, tables, sequences, routines, functions, and events before importing.</li>
  <li>SQLite uses its native <code class="language-plaintext highlighter-rouge">.backup</code> and <code class="language-plaintext highlighter-rouge">.restore</code> APIs, checks the downloaded database before touching the target, and runs <code class="language-plaintext highlighter-rouge">quick_check</code> again afterward.</li>
</ul>

<p>The file restore runs before the database restore. That matters when a Rails SQLite database and file-backed Active Storage live on the same volume: the clean SQLite backup stays separate from the raw database, WAL, and shared-memory files, and restoring the files cannot delete the database that was just restored.</p>

<p>Production restores require the application, jobs, and other database writers to be stopped. Restore drills use scratch databases, scratch SQLite files, and scratch file paths instead of touching the live targets. The point is not to make destructive operations feel casual. It is to make the safe procedure obvious and repeatable.</p>

<h2 id="tested-beyond-postgresql">Tested beyond PostgreSQL</h2>

<p>The Chat with Work migration was PostgreSQL. I do not have a production MySQL or SQLite migration story to pretend otherwise.</p>

<p>What 1.0 has instead is an exact backup-and-restore matrix that builds the real accessory image and exercises:</p>

<ul>
  <li>PostgreSQL 14, 15, 16, 17, and 18;</li>
  <li>MySQL 8.0 and 8.4;</li>
  <li>MariaDB 10.11, 11.4, and 11.8;</li>
  <li>SQLite in WAL mode, including backup and restore through restic’s rclone backend.</li>
</ul>

<p>The matrix creates data, views, routines, functions, triggers, events, custom PostgreSQL schemas, and MariaDB sequences. It adds objects that exist only in the restore target, restores the snapshot, and checks that the stored objects work and the target-only objects are gone.</p>

<p>The accessory image ships for amd64 and arm64. It includes matching PostgreSQL clients, the MariaDB client tools used for MySQL and MariaDB, SQLite, restic, rclone, and SSH. Restic’s native repositories still work, SFTP works with a dedicated SSH key, and rclone opens the rest of its storage providers without turning kamal-backup into a storage abstraction of its own.</p>

<h2 id="the-same-small-kamal-accessory">The same small Kamal accessory</h2>

<p>The shape of the project has not changed since <a href="/kamal-backup/">I first released it</a>: a Ruby gem gives your Rails repository a CLI, and a Docker image runs the scheduled backups beside your application as a Kamal accessory.</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">group</span> <span class="ss">:development</span> <span class="k">do</span>
  <span class="n">gem</span> <span class="s2">"kamal-backup"</span><span class="p">,</span> <span class="s2">"~&gt; 1.0"</span>
<span class="k">end</span>
</code></pre></div></div>

<div class="language-sh highlighter-rouge"><div class="highlight"><pre class="highlight"><code>bundle <span class="nb">install
</span>bundle <span class="nb">exec </span>kamal-backup init
bundle <span class="nb">exec </span>kamal-backup validate
bin/kamal accessory boot backup
bundle <span class="nb">exec </span>kamal-backup backup <span class="nt">--force</span>
bundle <span class="nb">exec </span>kamal-backup drill production latest
</code></pre></div></div>

<p>It backs up one or more PostgreSQL, MySQL, MariaDB, or SQLite databases, plus the file paths you explicitly configure for file-backed Active Storage. Restic handles encryption, deduplication, retention, and repository integrity. <code class="language-plaintext highlighter-rouge">kamal-backup evidence</code> turns the configuration, latest snapshots, checks, drills, retention, and tool versions into redacted JSON for the next person who asks whether the backups actually work.</p>

<p>Version 1.0 does not mean backups are finished. It means the interface and the restore promises are ready to depend on.</p>

<p>Read the <a href="https://kamal-backup.dev">documentation</a>, look through the <a href="https://kamal-backup.dev/restore/">restore guide</a>, and get the source on <a href="https://github.com/crmne/kamal-backup">GitHub</a>.</p>

<p>Then run a restore drill. The green backup log is the beginning of the test, not the end.</p>]]></content><author><name>Carmine Paolino</name></author><category term="Ruby" /><category term="Rails" /><category term="Kamal" /><category term="Backups" /><category term="Open Source" /><summary type="html"><![CDATA[kamal-backup 1.0 brings exact Rails restores, restore drills, and PostgreSQL, MySQL, MariaDB, SQLite, SFTP, and rclone support to Kamal.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://paolino.me/images/kamal-backup.png" /><media:content medium="image" url="https://paolino.me/images/kamal-backup.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">RubyLLM 2.0: Providers, Protocols, and Provider Gems</title><link href="https://paolino.me/rubyllm-2-0-providers-and-protocols/" rel="alternate" type="text/html" title="RubyLLM 2.0: Providers, Protocols, and Provider Gems" /><published>2026-08-27T00:00:00+00:00</published><updated>2026-10-04T17:42:40+00:00</updated><id>https://paolino.me/rubyllm-2-0-providers-and-protocols</id><content type="html" xml:base="https://paolino.me/rubyllm-2-0-providers-and-protocols/"><![CDATA[<p>RubyLLM 2.0 is almost ready. It isn’t out yet, but it will be soon, and I have been looking forward to showing you what is in it.</p>

<p>There is a lot in this release. Too much for one enormous announcement, and most of it deserves more than a bullet point. So this is the first in a series of posts about what’s coming in RubyLLM 2.0.</p>

<p>Let’s start with providers and protocols.</p>

<p>In 2.0, OpenAI uses the Responses API by default. Providers and protocols are separate things. Four new providers bring the total to seventeen. And if the provider you need is still missing, a new generator gives you a complete provider gem to start from.</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="no">RubyLLM</span><span class="p">.</span><span class="nf">chat</span><span class="p">(</span><span class="ss">model: </span><span class="s1">'gpt-5.4'</span><span class="p">)</span>                              <span class="c1"># OpenAI Responses API</span>
<span class="no">RubyLLM</span><span class="p">.</span><span class="nf">chat</span><span class="p">(</span><span class="ss">model: </span><span class="s1">'gpt-5.4'</span><span class="p">,</span> <span class="ss">protocol: :chat_completions</span><span class="p">)</span> <span class="c1"># same model, old API</span>
<span class="no">RubyLLM</span><span class="p">.</span><span class="nf">chat</span><span class="p">(</span><span class="ss">model: </span><span class="s1">'claude-opus-4-6'</span><span class="p">,</span> <span class="ss">provider: :vertexai</span><span class="p">)</span> <span class="c1"># Vertex AI, Anthropic protocol</span>
</code></pre></div></div>

<h2 id="a-provider-is-not-a-protocol">A provider is not a protocol</h2>

<p>A provider is the service you connect to: OpenAI, Mistral, Vertex AI, or one of the others. It knows the host, credentials, configuration, and model catalog.</p>

<p>A protocol is the API it speaks: Chat Completions, Responses, Anthropic, Gemini, Bedrock Converse, or Cohere. It knows how to build a request, parse the response, and handle streaming.</p>

<p>Mistral, DeepSeek, Perplexity, Ollama, and most self-hosted services all speak some version of OpenAI’s Chat Completions API. In 1.x, I handled that with inheritance. <code class="language-plaintext highlighter-rouge">Mistral &lt; OpenAI</code> reused the request code, but it also inherited a pile of OpenAI assumptions and then had to undo the ones that did not apply.</p>

<p>That was only half the problem. One protocol can be used by many providers, but one provider can also speak many protocols. OpenAI speaks Chat Completions and Responses; Vertex AI speaks Gemini, Claude, Mistral, and open models, all through different API shapes. The old design had no good way to express that.</p>

<p>In 2.0, providers register the protocols they speak and choose one for each model. Here is the chat-routing part of the Vertex AI provider, leaving its other operations out:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">class</span> <span class="nc">VertexAI</span> <span class="o">&lt;</span> <span class="no">Provider</span>
  <span class="n">protocol</span> <span class="ss">:gemini</span><span class="p">,</span> <span class="no">VertexAI</span><span class="o">::</span><span class="no">Gemini</span>
  <span class="n">protocol</span> <span class="ss">:anthropic</span><span class="p">,</span> <span class="no">VertexAI</span><span class="o">::</span><span class="no">Anthropic</span>
  <span class="n">protocol</span> <span class="ss">:mistral</span><span class="p">,</span> <span class="no">VertexAI</span><span class="o">::</span><span class="no">Mistral</span>
  <span class="n">protocol</span> <span class="ss">:chat_completions</span><span class="p">,</span> <span class="no">VertexAI</span><span class="o">::</span><span class="no">ChatCompletions</span>

  <span class="k">def</span> <span class="nf">protocol_for</span><span class="p">(</span><span class="n">model</span><span class="p">,</span> <span class="o">**</span><span class="p">)</span>
    <span class="k">case</span> <span class="n">model</span><span class="p">.</span><span class="nf">id</span>
    <span class="k">when</span> <span class="sr">%r{/}</span> <span class="k">then</span> <span class="n">protocols</span><span class="p">[</span><span class="ss">:chat_completions</span><span class="p">]</span>
    <span class="k">when</span> <span class="sr">/\Aclaude/</span> <span class="k">then</span> <span class="n">protocols</span><span class="p">[</span><span class="ss">:anthropic</span><span class="p">]</span>
    <span class="k">when</span> <span class="no">VertexAI</span><span class="o">::</span><span class="no">Mistral</span><span class="o">::</span><span class="no">MODELS</span> <span class="k">then</span> <span class="n">protocols</span><span class="p">[</span><span class="ss">:mistral</span><span class="p">]</span>
    <span class="k">else</span> <span class="k">super</span>
    <span class="k">end</span>
  <span class="k">end</span>
<span class="k">end</span>
</code></pre></div></div>

<p>So Claude on Vertex AI speaks Anthropic. <code class="language-plaintext highlighter-rouge">meta/llama-3.3-70b-instruct-maas</code> speaks Chat Completions. Gemini speaks Gemini. The model changes, the wire format changes, and your application does not.</p>

<h2 id="openai-uses-responses-by-default">OpenAI uses Responses by default</h2>

<p>OpenAI now has two chat APIs. RubyLLM 2.0 supports both, but defaults to Responses.</p>

<p>Responses gives RubyLLM access to encrypted reasoning content, provider-run tools, and newer OpenAI features. The application can use those features through the same chat API.</p>

<p>If you still need Chat Completions, choose it for one chat:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">chat</span> <span class="o">=</span> <span class="no">RubyLLM</span><span class="p">.</span><span class="nf">chat</span><span class="p">(</span><span class="ss">model: </span><span class="s1">'gpt-5.4'</span><span class="p">,</span> <span class="ss">protocol: :chat_completions</span><span class="p">)</span>
</code></pre></div></div>

<p>Or keep it as the default for OpenAI:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="no">RubyLLM</span><span class="p">.</span><span class="nf">configure</span> <span class="k">do</span> <span class="o">|</span><span class="n">config</span><span class="o">|</span>
  <span class="n">config</span><span class="p">.</span><span class="nf">openai_protocol</span> <span class="o">=</span> <span class="ss">:chat_completions</span>
<span class="k">end</span>
</code></pre></div></div>

<p>An explicit <code class="language-plaintext highlighter-rouge">protocol:</code> wins over configuration, and configuration wins over the provider default.</p>

<p>The same protocol code is useful outside OpenAI. xAI’s primary API now looks like Responses, so its RubyLLM provider gets streaming, encrypted reasoning, and server tools from the same implementation. Azure and DeepSeek can opt into Responses too.</p>

<h2 id="one-bedrock-endpoint-three-apis">One Bedrock endpoint, three APIs</h2>

<p>AWS Bedrock Mantle makes the difference between a provider and a protocol very obvious. You connect to one AWS service, but the API changes with the model.</p>

<p>Claude uses Anthropic’s Messages API. Other models use OpenAI’s Responses or Chat Completions formats. They share the same catalog, authentication, and host; the model metadata tells RubyLLM which protocol to use.</p>

<p>Even the model catalogs disagree. Mantle spells some model IDs differently from Bedrock Converse and includes models that Converse does not know about at all.</p>

<p>Without protocol routing, switching models can also mean switching request formats. RubyLLM reads both catalogs, records which protocol each model speaks, and routes the request for you. The <code class="language-plaintext highlighter-rouge">RubyLLM.chat</code> API stays the same. You can even switch models in the middle of a conversation with <code class="language-plaintext highlighter-rouge">.with_model</code>, and RubyLLM switches protocols with it.</p>

<h2 id="four-new-providers">Four new providers</h2>

<p>RubyLLM 2.0 will ship with seventeen providers, up from thirteen in 1.16:</p>

<ul>
  <li><strong>Cohere</strong> with native chat, embeddings, reranking, and transcription.</li>
  <li><strong>Ollama Cloud</strong> with Ollama’s API against its hosted model catalog. No local server required.</li>
  <li><strong>ElevenLabs</strong> for speech, transcription, and image and video generation.</li>
  <li><strong>Deepgram</strong> for speech and transcription.</li>
</ul>

<h2 id="a-complete-provider-in-one-small-file">A complete provider in one small file</h2>

<p>Once the protocol handles the wire format, a provider can be very small. Here is the entire Mistral provider in RubyLLM 2.0:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">module</span> <span class="nn">RubyLLM</span>
  <span class="k">module</span> <span class="nn">Providers</span>
    <span class="k">class</span> <span class="nc">Mistral</span> <span class="o">&lt;</span> <span class="no">Provider</span>
      <span class="n">protocol</span> <span class="ss">:chat_completions</span><span class="p">,</span> <span class="no">ChatCompletions</span><span class="p">,</span> <span class="ss">batches: </span><span class="no">Mistral</span><span class="o">::</span><span class="no">ChatCompletions</span><span class="o">::</span><span class="no">Batches</span>
      <span class="n">protocol</span> <span class="ss">:conversations</span><span class="p">,</span> <span class="no">Conversations</span>
      <span class="n">protocol</span> <span class="ss">:files</span><span class="p">,</span> <span class="no">Protocols</span><span class="o">::</span><span class="no">Mistral</span><span class="o">::</span><span class="no">Files</span>

      <span class="k">def</span> <span class="nf">protocol_for</span><span class="p">(</span><span class="n">model</span><span class="p">,</span> <span class="ss">operation: </span><span class="kp">nil</span><span class="p">,</span> <span class="o">**</span><span class="p">)</span>
        <span class="k">return</span> <span class="no">Conversations</span> <span class="k">if</span> <span class="n">operation</span> <span class="o">==</span> <span class="ss">:paint</span>

        <span class="k">super</span>
      <span class="k">end</span>

      <span class="k">def</span> <span class="nf">api_base</span>
        <span class="vi">@config</span><span class="p">.</span><span class="nf">mistral_api_base</span> <span class="o">||</span> <span class="s1">'https://api.mistral.ai/v1'</span>
      <span class="k">end</span>

      <span class="k">def</span> <span class="nf">headers</span>
        <span class="p">{</span>
          <span class="s1">'Authorization'</span> <span class="o">=&gt;</span> <span class="s2">"Bearer </span><span class="si">#{</span><span class="vi">@config</span><span class="p">.</span><span class="nf">mistral_api_key</span><span class="si">}</span><span class="s2">"</span>
        <span class="p">}</span>
      <span class="k">end</span>

      <span class="k">def</span> <span class="nf">batch_cost_multiplier</span><span class="p">(</span><span class="o">**</span><span class="p">)</span> <span class="o">=</span> <span class="mf">0.5</span>

      <span class="k">class</span> <span class="o">&lt;&lt;</span> <span class="nb">self</span>
        <span class="k">def</span> <span class="nf">capabilities</span>
          <span class="no">Mistral</span><span class="o">::</span><span class="no">Capabilities</span>
        <span class="k">end</span>

        <span class="k">def</span> <span class="nf">models_dev_alias</span><span class="p">(</span><span class="o">...</span><span class="p">)</span>
          <span class="no">Mistral</span><span class="o">::</span><span class="no">Models</span><span class="p">.</span><span class="nf">models_dev_alias</span><span class="p">(</span><span class="o">...</span><span class="p">)</span>
        <span class="k">end</span>

        <span class="k">def</span> <span class="nf">configuration_options</span>
          <span class="sx">%i[mistral_api_key mistral_api_base]</span>
        <span class="k">end</span>

        <span class="k">def</span> <span class="nf">configuration_requirements</span>
          <span class="sx">%i[mistral_api_key]</span>
        <span class="k">end</span>
      <span class="k">end</span>
    <span class="k">end</span>
  <span class="k">end</span>
<span class="k">end</span>
</code></pre></div></div>

<p>That’s the whole file. Request formatting and parsing live in the protocol classes, so this adapter can concentrate on endpoints, authentication, and choosing the right protocol.</p>

<h2 id="build-the-next-provider-yourself">Build the next provider yourself</h2>

<p>The provider and protocol split pays off outside RubyLLM too. The most common feature request is another provider. In 2.0, you do not have to wait for me to add one.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>ruby_llm provider-gem Acme <span class="nt">--api-base</span> https://api.acme.ai/v1
</code></pre></div></div>

<p>That command creates <code class="language-plaintext highlighter-rouge">ruby_llm-providers-acme</code>, initializes Git, installs the bundle, and gives you an ignored <code class="language-plaintext highlighter-rouge">.env</code>, provider registration, a model-catalog task, live-recording specs, RuboCop, Flay, ArchSpec, and CI across every supported Ruby version. It gets the same kind of care as RubyLLM itself, already wired up.</p>

<p>The important part is what you do not have to build. If Acme speaks Chat Completions, it reuses RubyLLM’s existing protocol for requests, responses, streaming, tools, and errors. If it speaks another familiar API, pass <code class="language-plaintext highlighter-rouge">--dialect responses</code>, <code class="language-plaintext highlighter-rouge">anthropic</code>, <code class="language-plaintext highlighter-rouge">gemini</code>, <code class="language-plaintext highlighter-rouge">converse</code>, or <code class="language-plaintext highlighter-rouge">ollama</code>. The provider only needs to supply its host, authentication, model catalog, and any real quirks it has.</p>

<p>That is what the split makes possible. A new or smaller provider no longer needs another OpenAI-compatible implementation, another Anthropic-compatible implementation, or a growing pile of API-base switches and provider exceptions inside RubyLLM. It gets to reuse the protocol and remain a small adapter.</p>

<p>When it is ready, tell your users to add it to their Gemfile:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">gem</span> <span class="s1">'ruby_llm-providers-acme'</span><span class="p">,</span> <span class="ss">require: </span><span class="s1">'ruby_llm/providers/acme'</span>
</code></pre></div></div>

<p>With their API key configured, that is it. The gem registers itself, brings its model catalog, and works through the same <code class="language-plaintext highlighter-rouge">RubyLLM.chat</code> API as a built-in provider.</p>

<p>Once 2.0 is out, go ahead and try it yourself. I’ll save the complete tutorial for another post.</p>

<h2 id="a-model-registry-applications-can-rely-on">A model registry applications can rely on</h2>

<p>The model registry that RubyLLM uses for capabilities and pricing is now published at <a href="https://rubyllm.com/models.json">rubyllm.com/models.json</a>.</p>

<p>For the first time, anyone can download, inspect, or build on the same catalog RubyLLM uses itself.</p>

<p><a href="https://models.dev">models.dev</a> is an excellent source, but RubyLLM needs more than a copy of it. Every six hours, RubyLLM rebuilds its registry from models.dev and the providers’ own APIs, reconciles aliases, fills gaps, applies the few provider-specific corrections that remain, validates the result, and refuses suspicious regressions before publishing it.</p>

<p>RubyLLM applications use the same registry to validate model names, choose protocols, check capabilities, and price provider usage. That last part demands precision: if a price, modality, or capability is wrong, the answer your application gets is wrong too. I will cover the cost ledger in another post, but the registry is what makes it possible.</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="no">RubyLLM</span><span class="p">.</span><span class="nf">models</span><span class="p">.</span><span class="nf">refresh</span>
</code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">refresh</code> fetches the latest main registry and persists it. New models, prices, context windows, and capabilities can reach your application without waiting for the next gem release.</p>

<p>Provider gems can ship their own <code class="language-plaintext highlighter-rouge">models.json</code> too. RubyLLM loads it as a read-only fallback behind the main registry, so installing a provider gem is enough to use its models normally.</p>

<p>The provider gem’s models appear in <code class="language-plaintext highlighter-rouge">RubyLLM.models</code> and can be selected with the normal <code class="language-plaintext highlighter-rouge">model:</code> and <code class="language-plaintext highlighter-rouge">provider:</code> keywords.</p>

<p>The global <code class="language-plaintext highlighter-rouge">refresh</code> never refreshes or rewrites provider gem catalogs. Their authors update them with <code class="language-plaintext highlighter-rouge">rake models</code> inside the provider gem.</p>

<p>The important part is that none of this makes the public API more complicated. <code class="language-plaintext highlighter-rouge">RubyLLM.chat</code>, <code class="language-plaintext highlighter-rouge">embed</code>, <code class="language-plaintext highlighter-rouge">paint</code>, and the Rails integration still work the same way. Most applications get broader provider coverage through the APIs they already use. The new <code class="language-plaintext highlighter-rouge">protocol:</code> option is there for the times when you want to choose.</p>

<p>That is the first piece of RubyLLM 2.0. Next up: the agentic loop, and how 2.0 lets you stop it, resume it, and run it one step at a time.</p>

<p>The full guide to writing providers and protocols is at <a href="https://rubyllm.com/custom-providers/">rubyllm.com/custom-providers</a>.</p>]]></content><author><name>Carmine Paolino</name></author><category term="Ruby" /><category term="AI" /><category term="LLM" /><category term="Rails" /><category term="Open Source" /><category term="RubyLLM" /><summary type="html"><![CDATA[OpenAI moves to the Responses API by default, while a new provider architecture and gem generator make external providers first-class.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://paolino.me/images/rubyllm-2.0-providers.png" /><media:content medium="image" url="https://paolino.me/images/rubyllm-2.0-providers.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">ArchSpec 1.0: Executable Architecture Specification for Ruby’s Agentic Coding Era</title><link href="https://paolino.me/archspec/" rel="alternate" type="text/html" title="ArchSpec 1.0: Executable Architecture Specification for Ruby’s Agentic Coding Era" /><published>2026-08-20T00:00:00+00:00</published><updated>2026-08-20T09:34:39+00:00</updated><id>https://paolino.me/archspec</id><content type="html" xml:base="https://paolino.me/archspec/"><![CDATA[<p>More and more code is written by a model. Tests still tell you it works. RuboCop still tells you it’s tidy. Nothing tells you it still follows your architecture.</p>

<p>I released <a href="https://archspecrb.dev">ArchSpec</a> 1.0 today. It’s an architecture linter for Ruby and Rails. You declare your components and boundaries in one file, and every change gets checked, whether a person or an agent wrote it.</p>

<p><em>This is part of my push towards making Ruby one of the best languages to build with AI. <a href="https://rubyllm.com">RubyLLM</a> is one piece. <a href="/schematist/">Schematist</a> is another. <a href="/solid-queue-doesnt-need-a-thread-per-job/">Making the default Rails job queue fiber-based</a> is another.</em></p>

<h2 id="people-and-ais-take-shortcuts">People and AIs take shortcuts</h2>

<p>An agent or a person that’s in a hurry or doesn’t fully understand your architecture takes shortcuts.</p>

<p>The shortcuts work. They pass tests, implement features, and <em>cross your boundaries</em>. Months later, you realise your beautifully crafted architecture is now a patched mess.</p>

<p>Or, perhaps, you’re starting a new project and you want to ensure that the agent is using a <em>good</em> architecture, without having to police it at every step.</p>

<p>So you write it down in prompts and <code class="language-plaintext highlighter-rouge">AGENTS.md</code>. It helps, but it gets buried in its context window and something slips. Again, then again.</p>

<p>RuboCop reads your code and enforces a style. <a href="https://herb-tools.dev">Herb</a> does it for templates. Nothing did it for architecture. Until now.</p>

<h2 id="archspec-your-architecture-in-one-file">ArchSpec: your architecture in one file</h2>

<p>Declare your components and their rules in an <code class="language-plaintext highlighter-rouge">Archspec.rb</code> at the root of the project:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">component</span> <span class="ss">:models</span><span class="p">,</span> <span class="ss">in: </span><span class="s2">"app/models/**/*.rb"</span>
<span class="n">component</span> <span class="ss">:controllers</span><span class="p">,</span> <span class="ss">in: </span><span class="s2">"app/controllers/**/*.rb"</span>
<span class="n">component</span> <span class="ss">:services</span><span class="p">,</span> <span class="ss">in: </span><span class="s2">"app/services/**/*.rb"</span>

<span class="n">models</span><span class="p">.</span><span class="nf">cannot_use</span> <span class="ss">:controllers</span>
<span class="n">services</span><span class="p">.</span><span class="nf">cannot_call</span> <span class="ss">:render</span><span class="p">,</span> <span class="ss">:redirect_to</span><span class="p">,</span> <span class="ss">receiver: :none</span>
<span class="n">controllers</span><span class="p">.</span><span class="nf">can_only_use</span> <span class="ss">:models</span><span class="p">,</span> <span class="ss">:services</span>
</code></pre></div></div>

<p>Then <code class="language-plaintext highlighter-rouge">archspec check</code> verifies every change. Models can’t reach into controllers. Domain code can’t touch adapters. Query objects can’t call <code class="language-plaintext highlighter-rouge">save!</code>. A pack exposes a public API and keeps everything else private. A directory has to stay empty, and says why.</p>

<p>If you’d rather not write rules at all, start from a preset:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">architecture</span> <span class="ss">:vanilla_rails</span>
</code></pre></div></div>

<p>That one line is the 37signals playbook: rich models, no service objects, no form objects, no policy objects, and <code class="language-plaintext highlighter-rouge">app/services</code> fails the build with a reason if anything shows up in it. There are presets for Rails, layered, hexagonal, clean architecture, modular monoliths, CQRS, and event-driven too.</p>

<h2 id="static-analysis-not-ai">Static Analysis, Not AI</h2>

<p>I’m the author of RubyLLM so you’d think this uses AI.</p>

<p>Nope. <em>ArchSpec doesn’t use AI</em>.</p>

<p>Here’s how it works: Prism parses your Ruby, then ArchSpec extracts facts, references, inheritance, mixins, calls, definitions, and evaluates your rules against them. It’s deterministic, it’s offline, and it’s fast enough that you’ll leave it on: the full Discourse app, 1,899 files, was checked in 2.5 seconds, without booting the app.</p>

<p>Prism is its only runtime dependency. No Rails, no ActiveSupport, nothing else, so it works on any Ruby codebase. RubyLLM is a plain gem and it’s been the main proving ground since June.</p>

<p>It also won’t guess. ArchSpec doesn’t try to infer the “true” design pattern of arbitrary Ruby. You describe the architecture you want, and it tells you whether the code still matches. The AI is on the other side of the loop, writing the code that gets checked.</p>

<h2 id="failures-an-agent-can-act-on">Failures an Agent Can Act On</h2>

<p>When a rule breaks, you get this:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>[error] models must not depend on controllers [dependencies.forbid]

app/models/user.rb:3:5

    2 │   def admin_path
  → 3 │     UsersController.admin_path_for(self)
      │     ^~~~~~~~~~~~~~~
    4 │   end

  note: User references UsersController

1 architecture violation found.
</code></pre></div></div>

<p>The format is a deliberate homage to clang and to Herb. Exact location, the offending span underlined, the evidence as a note, the rule id in brackets so you can suppress it narrowly.</p>

<p>A human reads it at a glance. An agent gets everything it needs to fix its own mistake without asking you: the file, the line, the rule, and why.</p>

<h2 id="what-it-caught-in-rubyllm">What It Caught in RubyLLM</h2>

<p>I added ArchSpec checks to <a href="https://rubyllm.com">RubyLLM</a> <a href="https://github.com/crmne/ruby_llm/commit/f1cf3b0e92e3e9244a94a2c1b5c7d4f2716d2aae">2 months ago</a>, in CI and as a pre-commit hook, and it has been instrumental in the big Protocol/Provider separation that’s coming in RubyLLM 2.0.</p>

<p>A protocol is a wire format, like Chat Completions, Responses, Anthropic’s Messages API, Gemini, or Bedrock Converse. A provider is an account you can talk to, like OpenAI, Azure, DeepSeek, or Ollama.</p>

<p>DeepSeek speaks Chat Completions. VertexAI speaks four: Gemini, Anthropic, Mistral, and Chat Completions. Writing each Protocol once is the reason the gem supports as many providers as it does.</p>

<p>That distinction is easy to state and easy to erode. The shortcut is to put a piece of wire format inside the provider that needs it, because right now that’s the only provider that needs it. Not on my watch:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">providers</span><span class="p">.</span><span class="nf">cannot_reference_constants</span> <span class="s1">'RubyLLM::Protocol'</span>
</code></pre></div></div>

<p>A provider can subclass a protocol family to change an endpoint or work around a quirk. Subclassing the bare <code class="language-plaintext highlighter-rouge">Protocol</code> means it’s inventing a wire format inside an adapter:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>[error] providers must not reference RubyLLM::Protocol [constants.forbid]

lib/ruby_llm/providers/elevenlabs/audio.rb:9:21

     8 │       # image endpoints, so those seams are left unimplemented.
  →  9 │       class Audio &lt; Protocol
       │                     ^~~~~~~~
    10 │         include ElevenLabs::Models

  note: RubyLLM::Providers::ElevenLabs::Audio inherits from Protocol

1 architecture violation found.
</code></pre></div></div>

<p>This actually happened while I was developing RubyLLM 2.0. The ElevenLabs audio API and the AWS InvokeModel embedding family had become complete wire formats hiding inside provider adapters. Moving them out also deleted extra code that only existed to paper over the misplacement. Win-win.</p>

<p>Here are some more examples from RubyLLM:</p>

<h3 id="make-contracts-only-static-analysis-can-actually-see">Make contracts only static analysis can actually see</h3>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">chat_protocol_families</span><span class="p">.</span><span class="nf">must_implement</span> <span class="ss">:render_payload</span><span class="p">,</span> <span class="ss">:completion_url</span><span class="p">,</span> <span class="ss">:parse_completion_body</span>
</code></pre></div></div>

<p>Every protocol family that speaks chat implements those three seams. The base class declares them abstract with <code class="language-plaintext highlighter-rouge">define_method</code>, so Ruby only raises at runtime and nothing catches it earlier. ArchSpec sees the definitions. A family that skips a seam fails the build instead of a request.</p>

<h3 id="keep-your-naming-conventions">Keep your naming conventions</h3>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">protocols</span><span class="p">.</span><span class="nf">method_names</span><span class="p">.</span><span class="nf">matching</span><span class="p">(</span><span class="sr">/\A(serialize|deserialize|to_wire|from_wire)_/</span><span class="p">)</span>
         <span class="p">.</span><span class="nf">forbidden</span><span class="p">(</span><span class="ss">because: </span><span class="s1">'serialize with render_*, deserialize with parse_*'</span><span class="p">)</span>
</code></pre></div></div>

<p>In RubyLLM, serialization methods are called <code class="language-plaintext highlighter-rouge">render_*</code>, deserialization <code class="language-plaintext highlighter-rouge">parse_*</code>. Exactly the kind of convention an agent breaks, because <code class="language-plaintext highlighter-rouge">serialize_payload</code> is a perfectly reasonable name and your rule is 200 lines in <code class="language-plaintext highlighter-rouge">AGENTS.md</code>.</p>

<h3 id="stop-slowly-decaying-api-parity">Stop slowly decaying API parity</h3>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">chat</span><span class="p">.</span><span class="nf">method_names</span><span class="p">.</span><span class="nf">matching</span><span class="p">(</span><span class="sr">/\Awith_(?&lt;option&gt;.+)/</span><span class="p">)</span>
    <span class="p">.</span><span class="nf">requires</span><span class="p">(</span><span class="s1">'%&lt;option&gt;s'</span><span class="p">,</span> <span class="ss">on: </span><span class="n">agent</span><span class="p">,</span> <span class="ss">scope: :class</span><span class="p">,</span>
              <span class="ss">except: </span><span class="sx">%i[with_temperature with_max_output_tokens]</span><span class="p">)</span>
</code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">Agent</code> is a declarative wrapper over <code class="language-plaintext highlighter-rouge">Chat</code>, so every <code class="language-plaintext highlighter-rouge">Chat#with_x</code> setter needs a matching class-level macro on <code class="language-plaintext highlighter-rouge">Agent</code>. Adding the setter is the interesting half. Adding the macro is not. Add <code class="language-plaintext highlighter-rouge">Chat#with_verbosity</code>, forget <code class="language-plaintext highlighter-rouge">Agent.verbosity</code>, and the build tells you before your users do.</p>

<h3 id="make-promises-to-your-users">Make promises to your users</h3>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">domain</span><span class="p">.</span><span class="nf">cannot_reference_constants</span> <span class="s1">'RubyLLM::ActiveRecord'</span>
</code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">require "ruby_llm"</code> works without Rails. That only stays true if the plain-Ruby objects never reach into the Rails integration. Without a check, you find out from a bug report.</p>

<p>Not every codebase needs a spec that long. <a href="https://chatwithwork.com">Chat with Work</a> runs its entire ruleset in one line, <code class="language-plaintext highlighter-rouge">architecture :vanilla_rails</code>, because the moat is the product and the code should stay plain and boring.</p>

<h2 id="but-isnt-this-packwerk">But Isn’t This Packwerk?</h2>

<p><a href="https://github.com/Shopify/packwerk">Packwerk</a> is good, and if packs are what you need, use it. ArchSpec covers that case with <code class="language-plaintext highlighter-rouge">architecture :modular_monolith</code>, and then keeps going.</p>

<p>Packwerk checks constant references between packages. By design it ignores method calls, and it leans on Zeitwerk to resolve names, which means it’s shaped like a Rails app. ArchSpec checks constant references too, plus calls, inheritance, mixins, required methods, cycles, and naming conventions, in one Ruby file, on any Ruby codebase.</p>

<p>Different scopes for different folks.</p>

<h2 id="getting-it-into-your-codebase">Getting It Into Your Codebase</h2>

<p>If your app is conventional, a preset is the whole file: <code class="language-plaintext highlighter-rouge">architecture :rails</code>, <code class="language-plaintext highlighter-rouge">architecture :vanilla_rails</code>, <code class="language-plaintext highlighter-rouge">architecture :hexagonal</code>.</p>

<p>If it isn’t, describe your architecture to a coding agent and have it draft the <code class="language-plaintext highlighter-rouge">Archspec.rb</code>. Agents are genuinely good at this. They can read the whole tree, they already know what your components are, and the DSL is small. Then read what it wrote, carefully, because the spec is the part you own, then add the parts the agents missed.</p>

<p>If one of our <code class="language-plaintext highlighter-rouge">architecture</code> presets is incomplete, or you’d like to add another one, send me an <a href="https://github.com/crmne/archspec/issues">issue</a> or a <a href="https://github.com/crmne/archspec/pulls">PR</a>. I want to make this the best architecture linter around.</p>

<p>Existing codebases have existing violations. <code class="language-plaintext highlighter-rouge">archspec check --update-todo</code> records them in a todo file, so the build goes green on today’s code and fails on new drift. Work the list down whenever.</p>

<p>Then put it in a pre-commit hook and a CI step. Every provider gem scaffolded by RubyLLM 2.0’s new provider generator is born with its own <code class="language-plaintext highlighter-rouge">Archspec.rb</code>, an archspec step in the default rake task, and the hook. New code starts life with an architecture spec the same way it starts with tests.</p>

<p>Keep those pesky agents with <code class="language-plaintext highlighter-rouge">--dangerously-skip-permissions</code> accountable.</p>

<h2 id="where-it-came-from">Where It Came From</h2>

<p>This started at RubyConf Austria in May. The <a href="https://radan.dev/news/ruby-conf-at">AI panel</a> and the hallway conversations around it, mostly with Chad Fowler and José Valim, kept landing in the same place from different directions: if models write the code, the human job concentrates in the decisions above the code. I’ve argued before that <a href="/engineering-is-not-dead/">engineering is not dead, because accountability isn’t</a>. Vienna sharpened the follow-up. What do you actually use to hold that line?</p>

<p>Flying home, I kept thinking about the tools we already have. So I built one, showed an early version to José, who was encouraging, and released 0.1 quietly in June.</p>

<p>It’s been running on every commit in ArchSpec itself, in RubyLLM, in <a href="https://chatwithwork.com">Chat with Work</a>, and in everything else I’ve made in Ruby ever since.</p>

<p>Every release is torture-tested against pinned checkouts of Discourse, Mastodon, and Basecamp’s Fizzy, where the per-rule diagnostic counts have to match recorded snapshots before anything ships.</p>

<h2 id="use-it">Use It</h2>

<div class="language-sh highlighter-rouge"><div class="highlight"><pre class="highlight"><code>bundle add archspec
bundle <span class="nb">exec </span>archspec init
bundle <span class="nb">exec </span>archspec check
</code></pre></div></div>

<p>Docs at <a href="https://archspecrb.dev">archspecrb.dev</a>, source on <a href="https://github.com/crmne/archspec">GitHub</a>. File issues for anything it gets wrong.</p>

<p>Agents can write the code. The architecture is still yours to keep.</p>]]></content><author><name>Carmine Paolino</name></author><category term="Ruby" /><category term="Rails" /><category term="AI" /><category term="Agents" /><category term="Open Source" /><category term="ArchSpec" /><category term="Architecture" /><summary type="html"><![CDATA[ArchSpec turns your architecture into an executable spec: declare components and boundaries in one Ruby file, and every change gets checked, whether a person or an agent wrote it.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://paolino.me/images/archspec-check.png" /><media:content medium="image" url="https://paolino.me/images/archspec-check.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry></feed>